One thing has always bothered me about MQTT in practice: devices publish where they want to, for example: tasmota/devices/14835A/...
The device ID is in there, fine. But every time I want to query or subscribe to that sensor, I first have to look up what device 14835A actually is. Is it my living room or is it the kitchen? Is it a temp sensor? Or is it a power meter?
With virtual topics, you can now define views on top of real topics. The sensor above can also be made available as: austria/vogler/office/temperature/..
Same data, two (or more) names. No republishing, no copying, no duplicated messages.
👉 Map a single topic, or mount a whole subtree
👉 Wildcard subscriptions work on the virtual tree
👉 Each node is read-only or read-write
That way you can have a location view, an asset view, or an ISA-95 style view of the same devices, all at the same time.
Now my question to you: is this useful, or should I drop it again? How do you deal with this today? Republishing in Node-RED, a strict UNS naming convention from day one, or just an Excel sheet? 😉
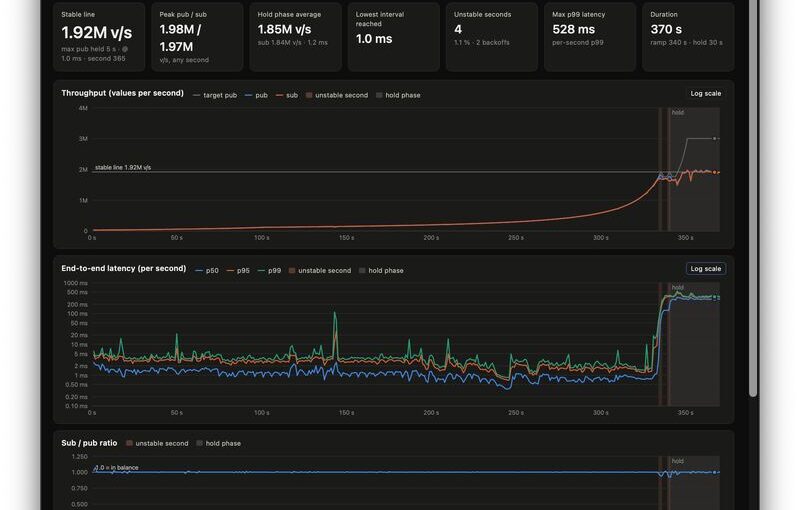
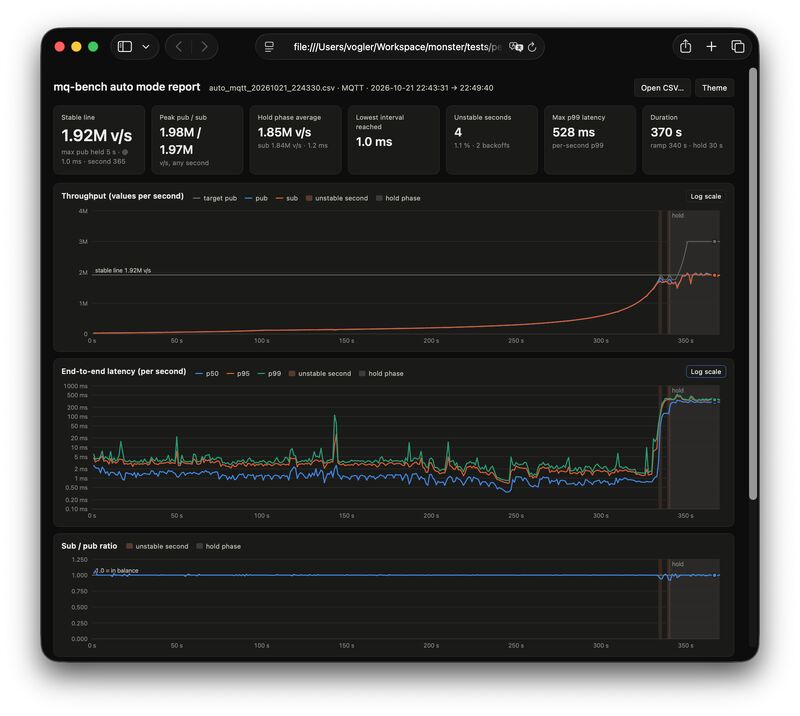
We optimized MonsterMQ Edge: ⚡️ 1.9M v/s Pub&Sub 💪 on a MacBook Air M4, and it persisted all values in memory! 🧠
👉 Clients and Server running on the same host
👉 Obviously QoS 0 and no retain flag
👉 No security enabled
Can we trust those numbers? 🙈 It looks unbelievable! With 1.9M v/s the latency went up, but at 1.3M v/s we had a stable latency of about 1.3 ms P95.
The test program is fully AI-created: 3,000 leaf topics with a 5-level tree structure, where clients are concurrently producing and consuming. It runs for 370s, increases and adapts the load, and writes a detailed benchmark protocol. See pic below!
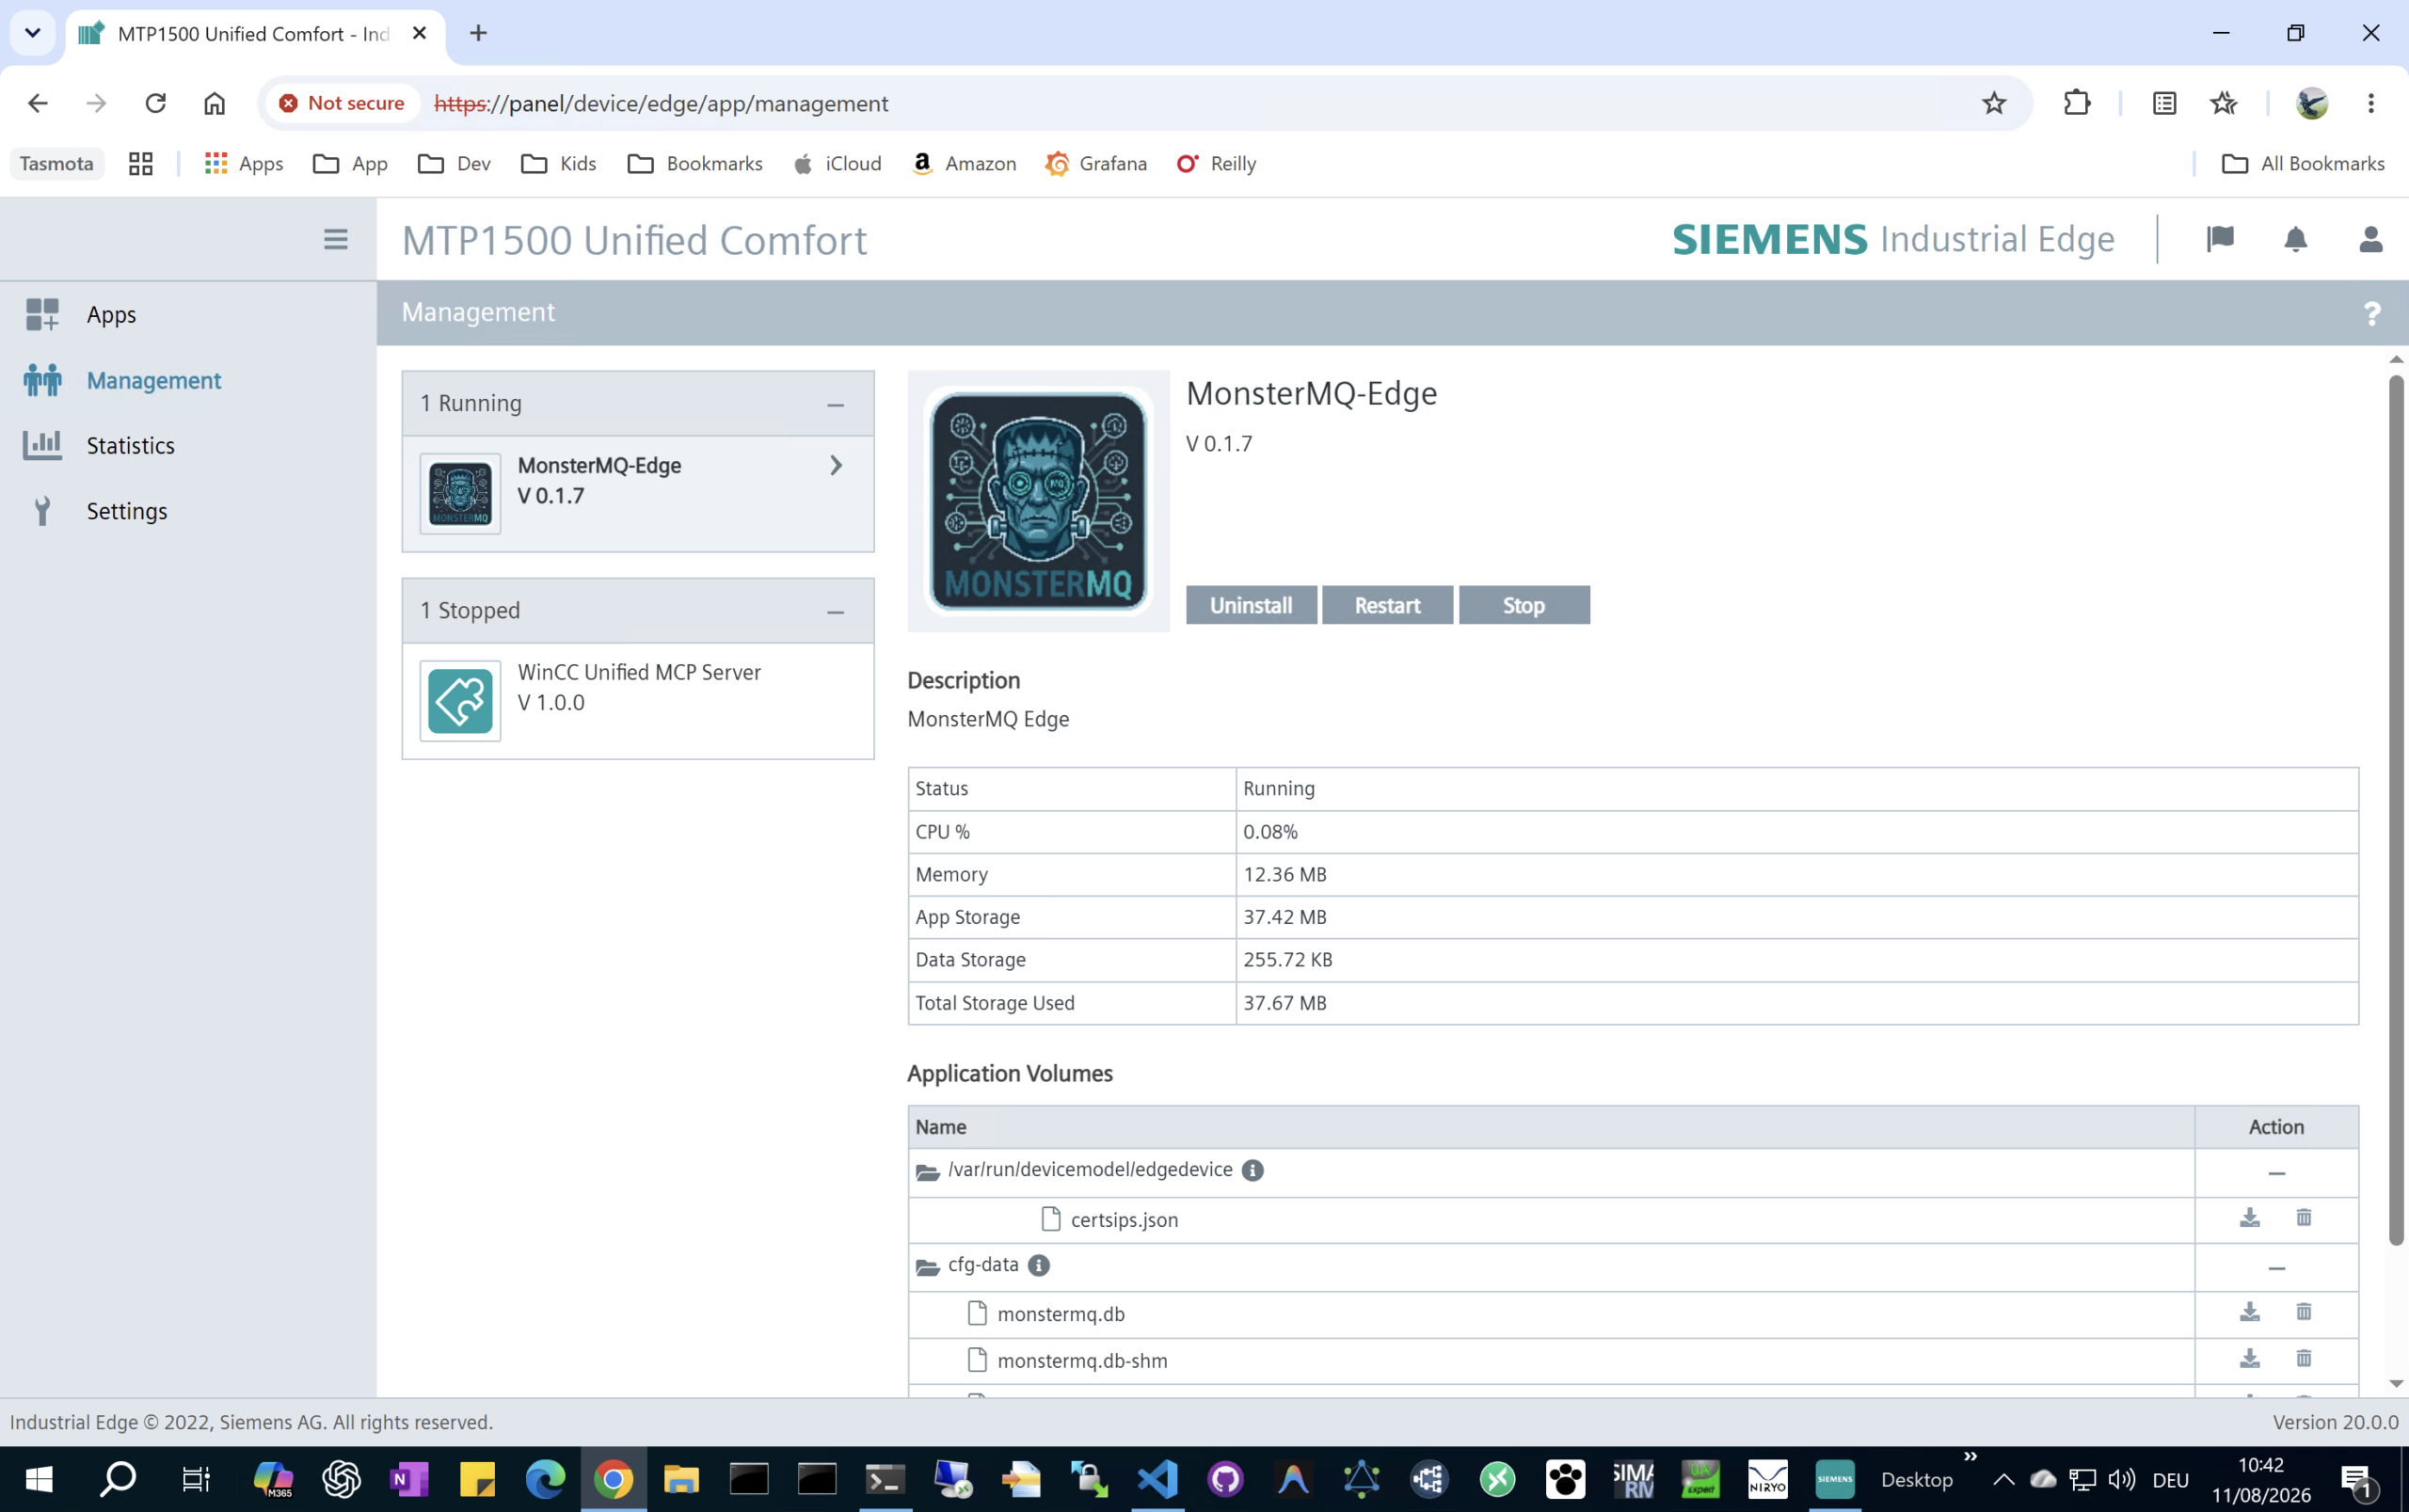
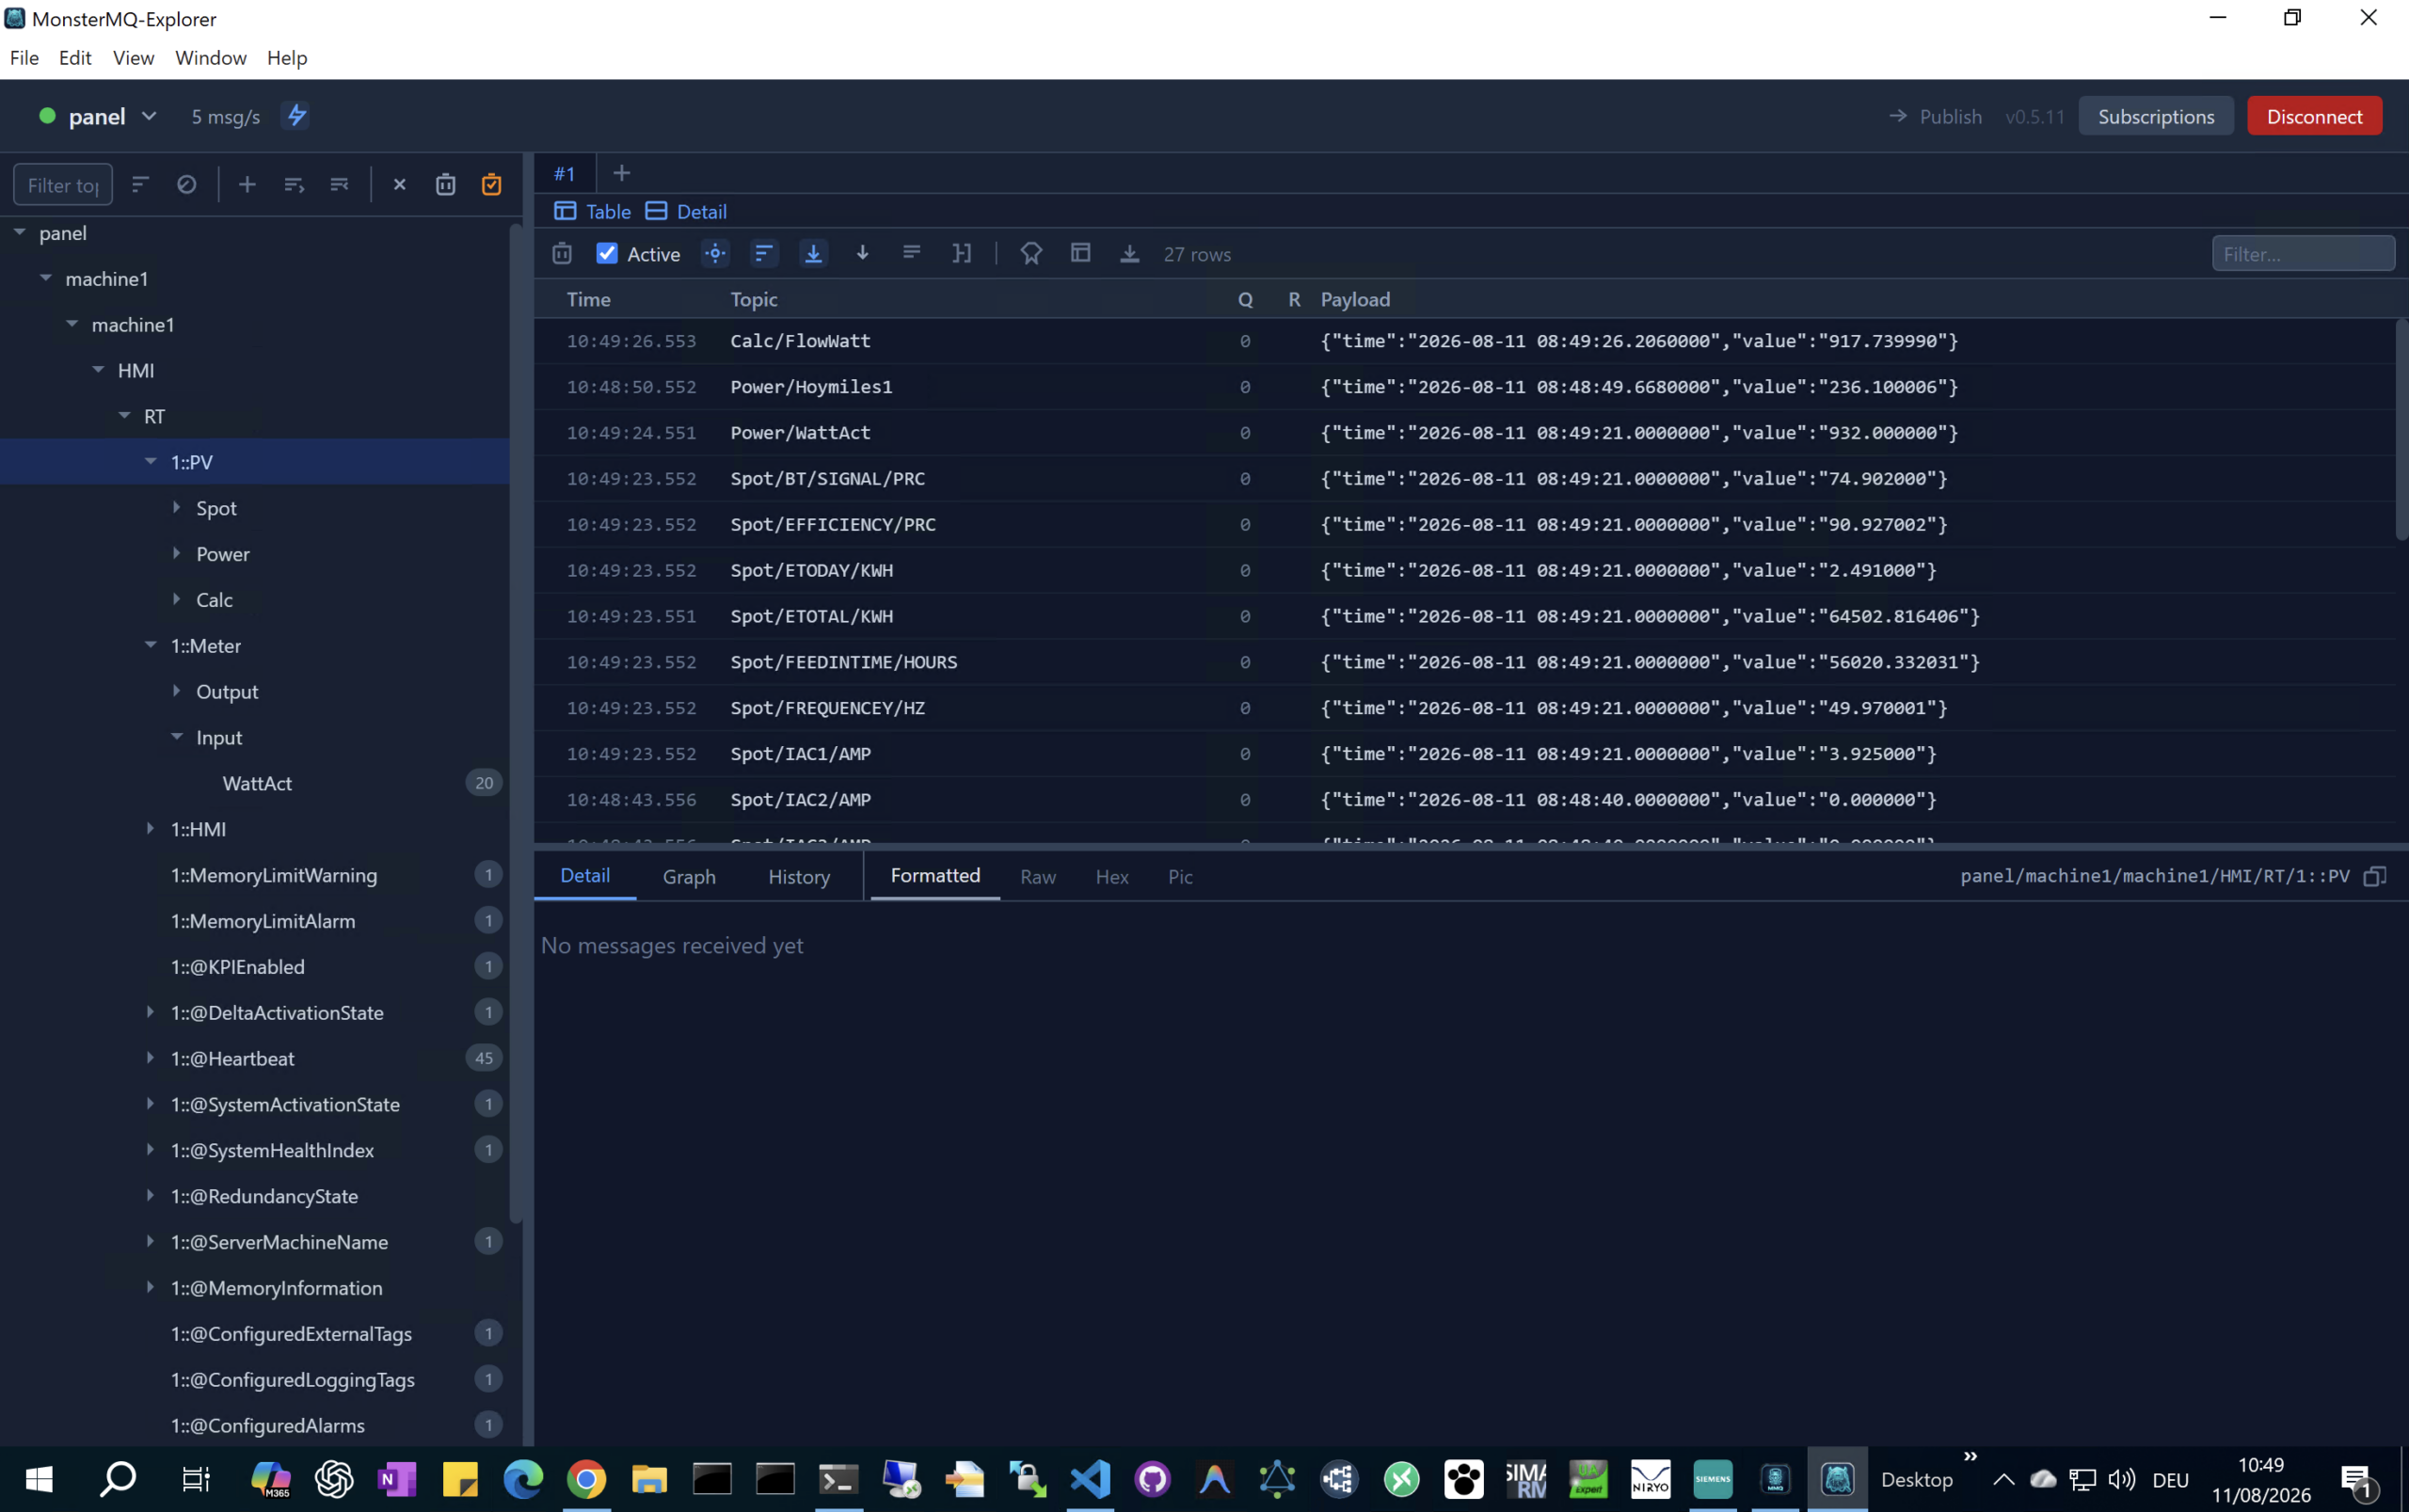
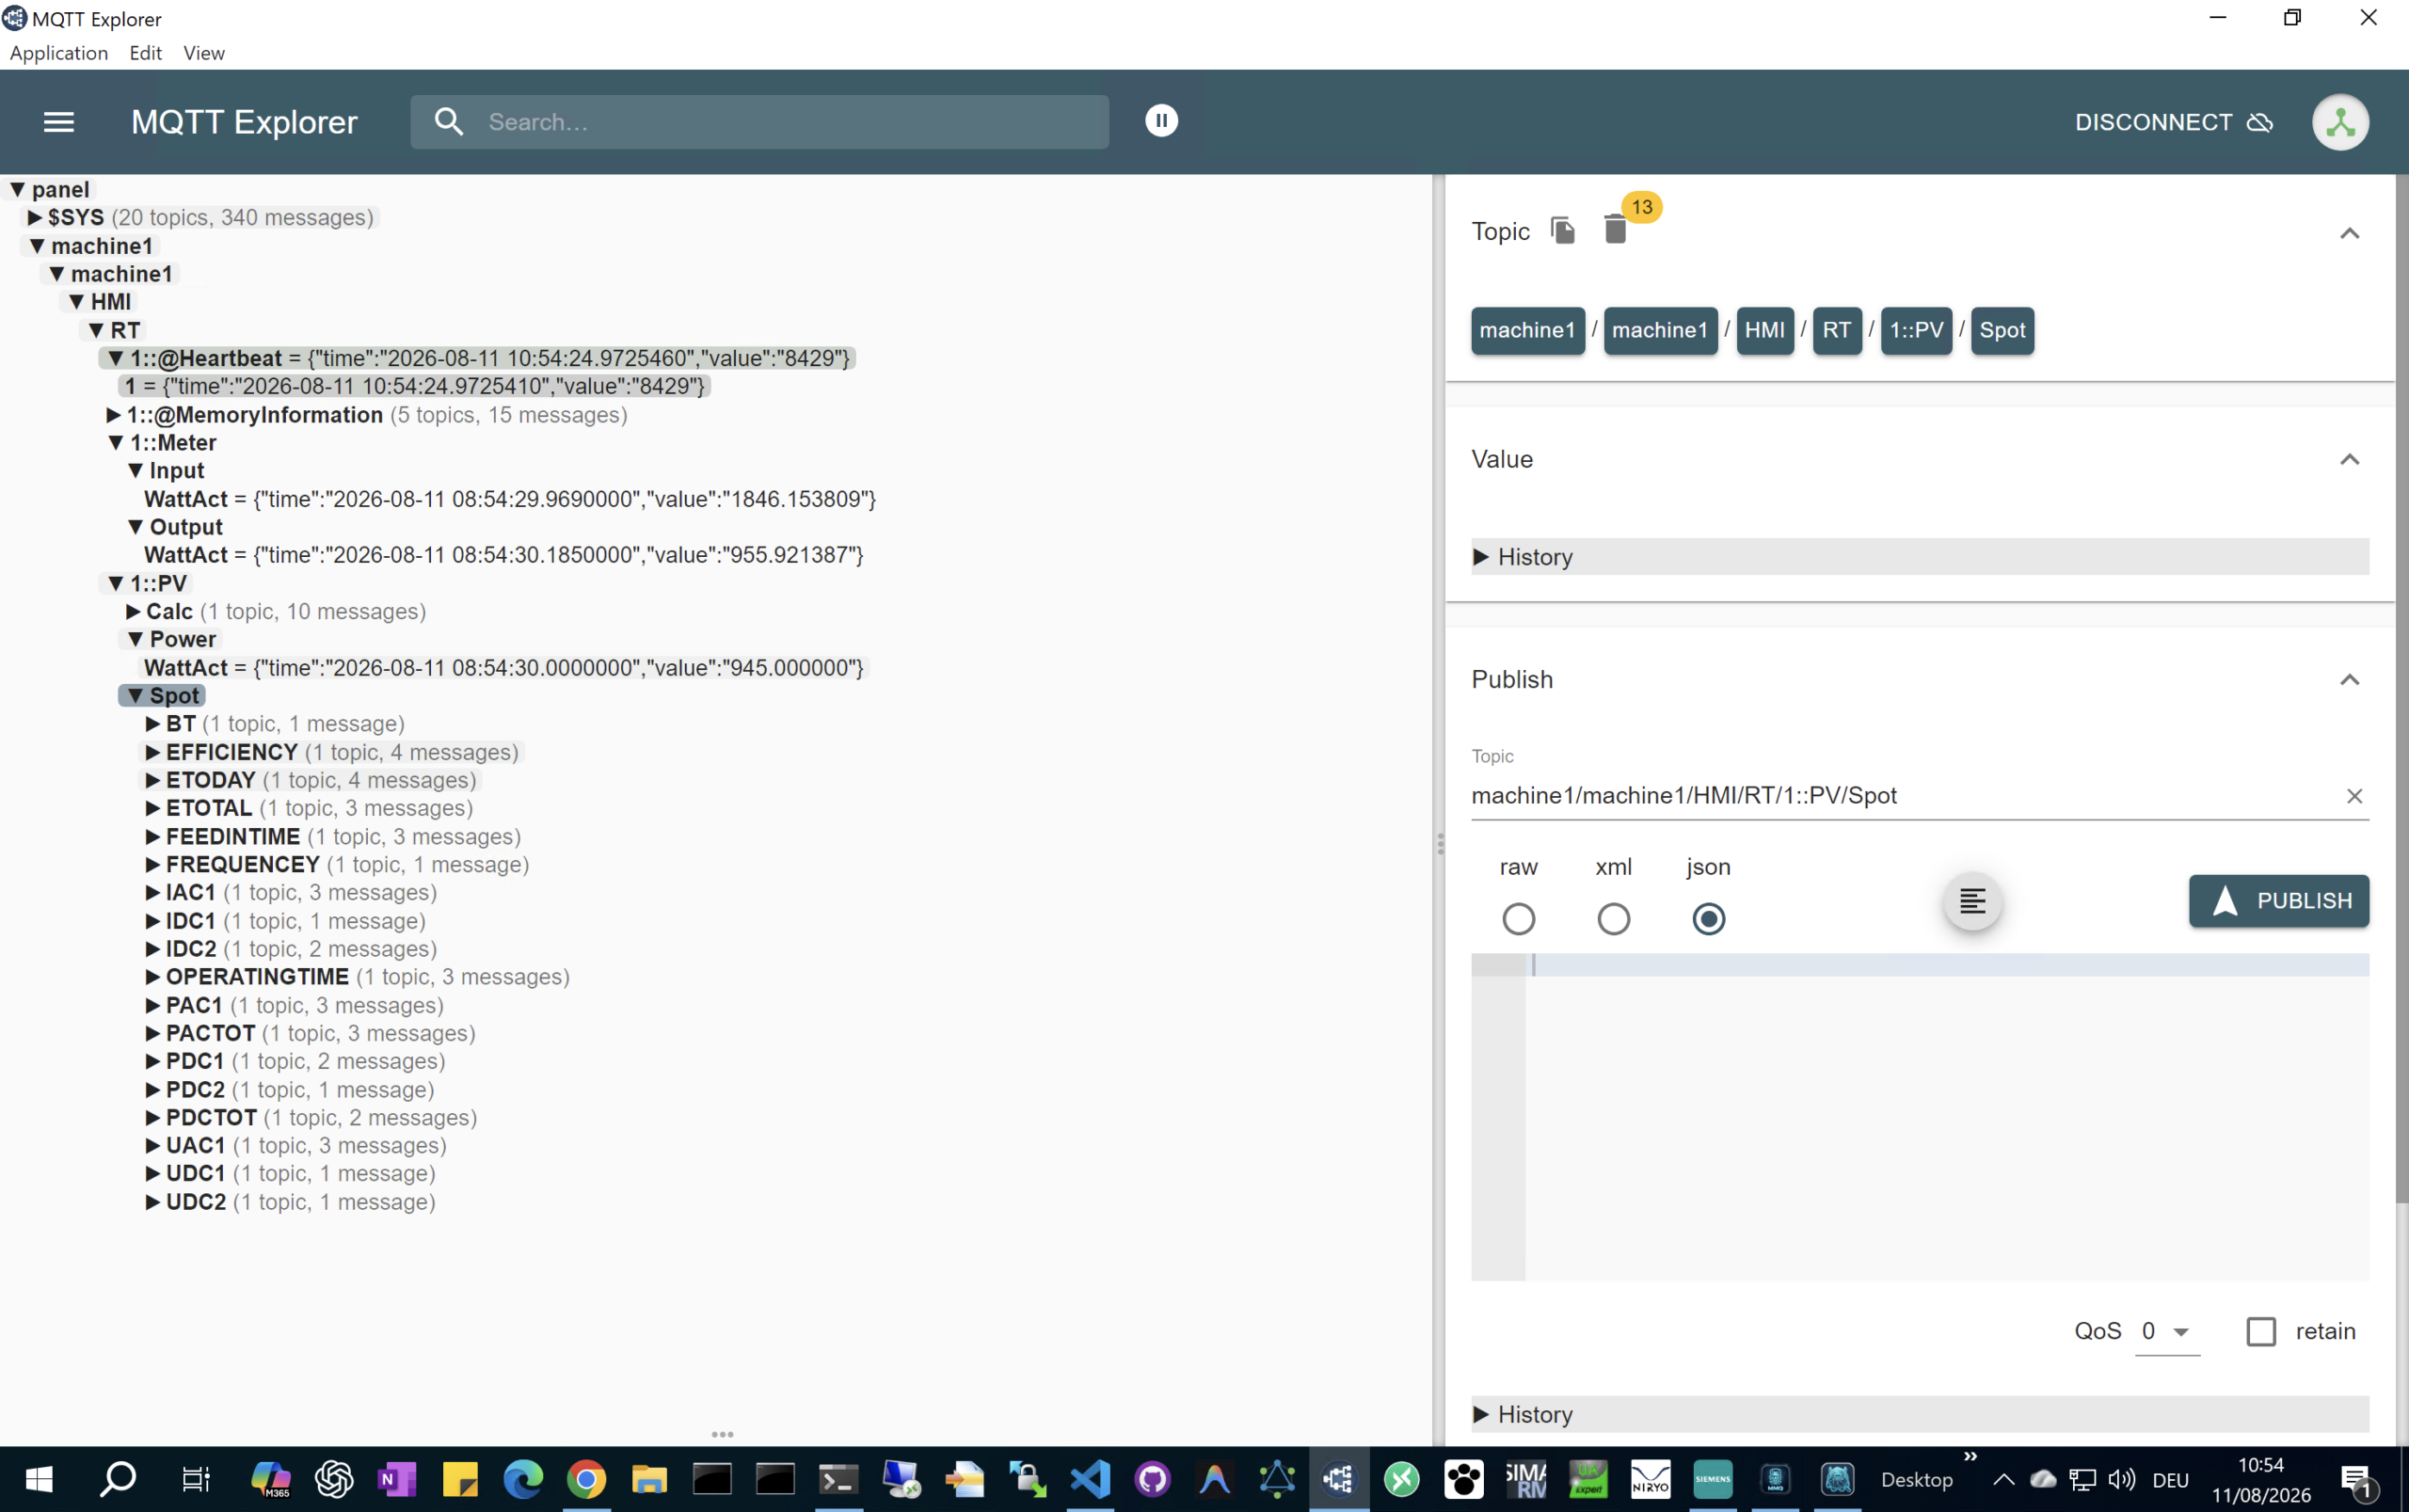
Vacation day 🏝️ I have published the MonsterMQ Edge MQTT Broker as an Industrial Edge app, bringing a lightweight, single-binary MQTT broker directly to your SIMATIC WinCC Unified Comfort Panels with a data connection to the runtime data.
2. Rename: Change the file extension from .tar to .app (MonsterMQ-Edge.app).
3. Upload & Start: Upload the .app file directly to your panel (with Industrial Edge enabled) and launch it.
4. Configure: Connect and manage the broker using the MonsterMQ Dashboard app, available under releases at MonsterMQ GitHub https://github.com/vogler75/monster-mq/releases
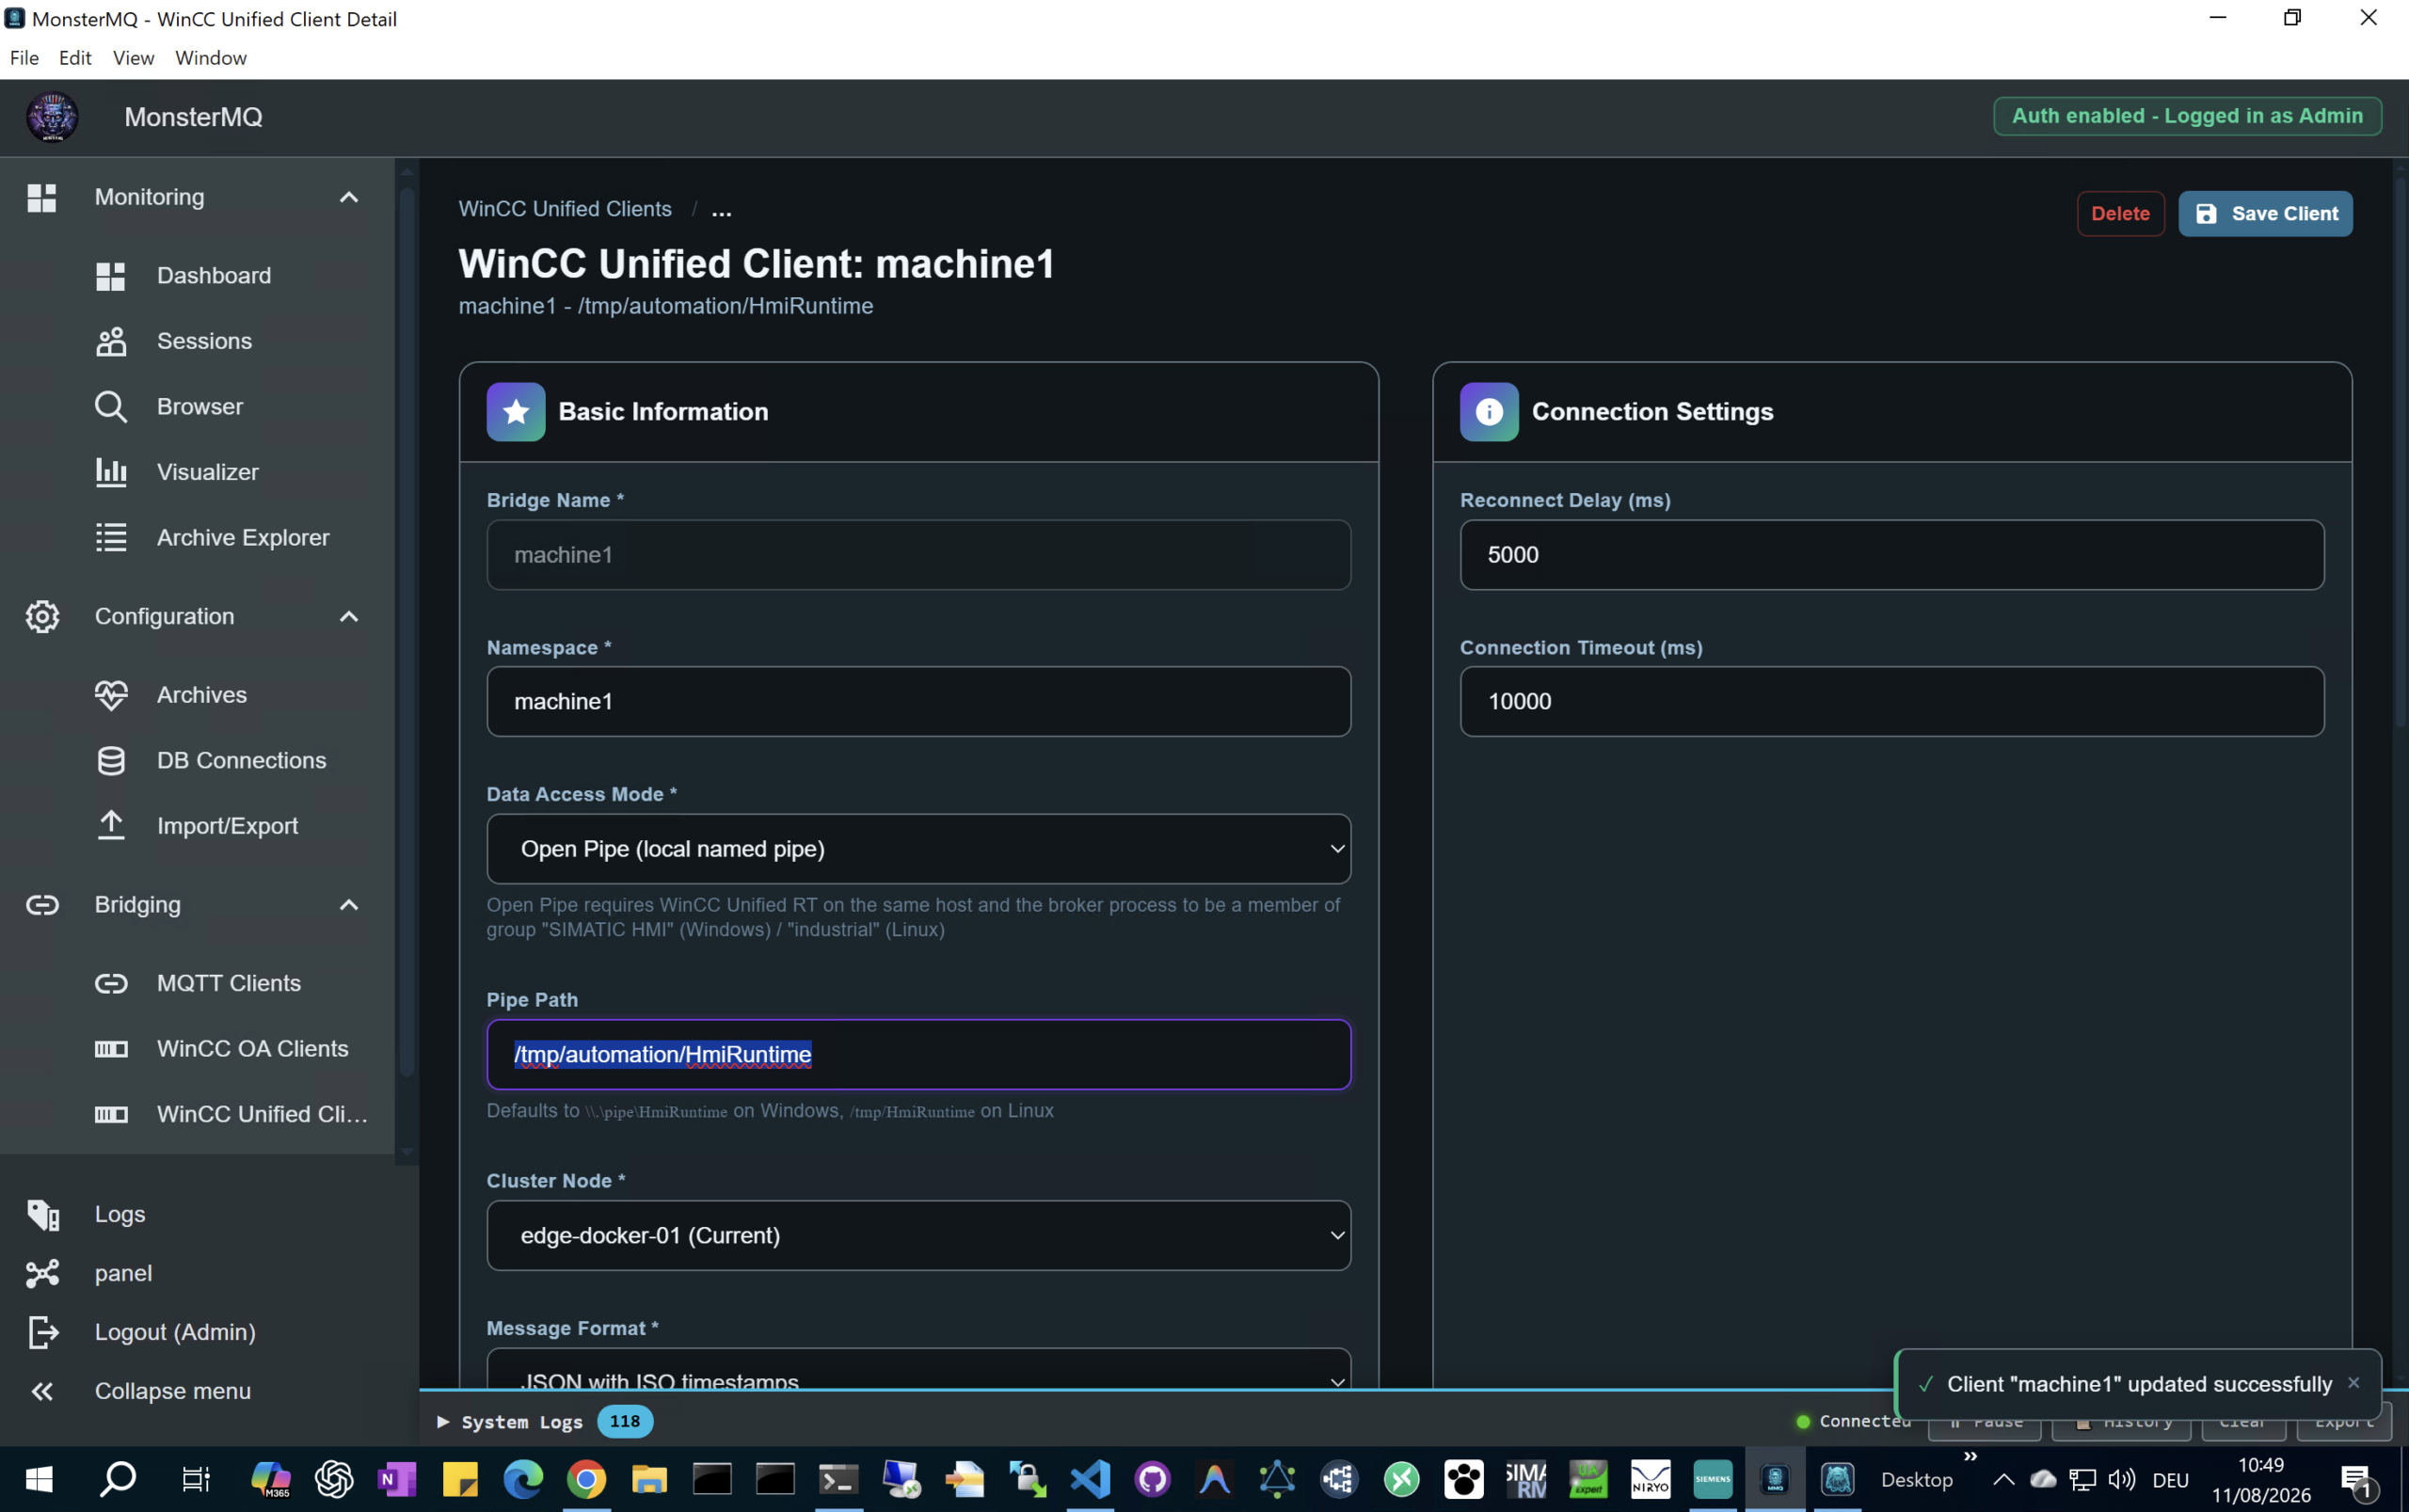
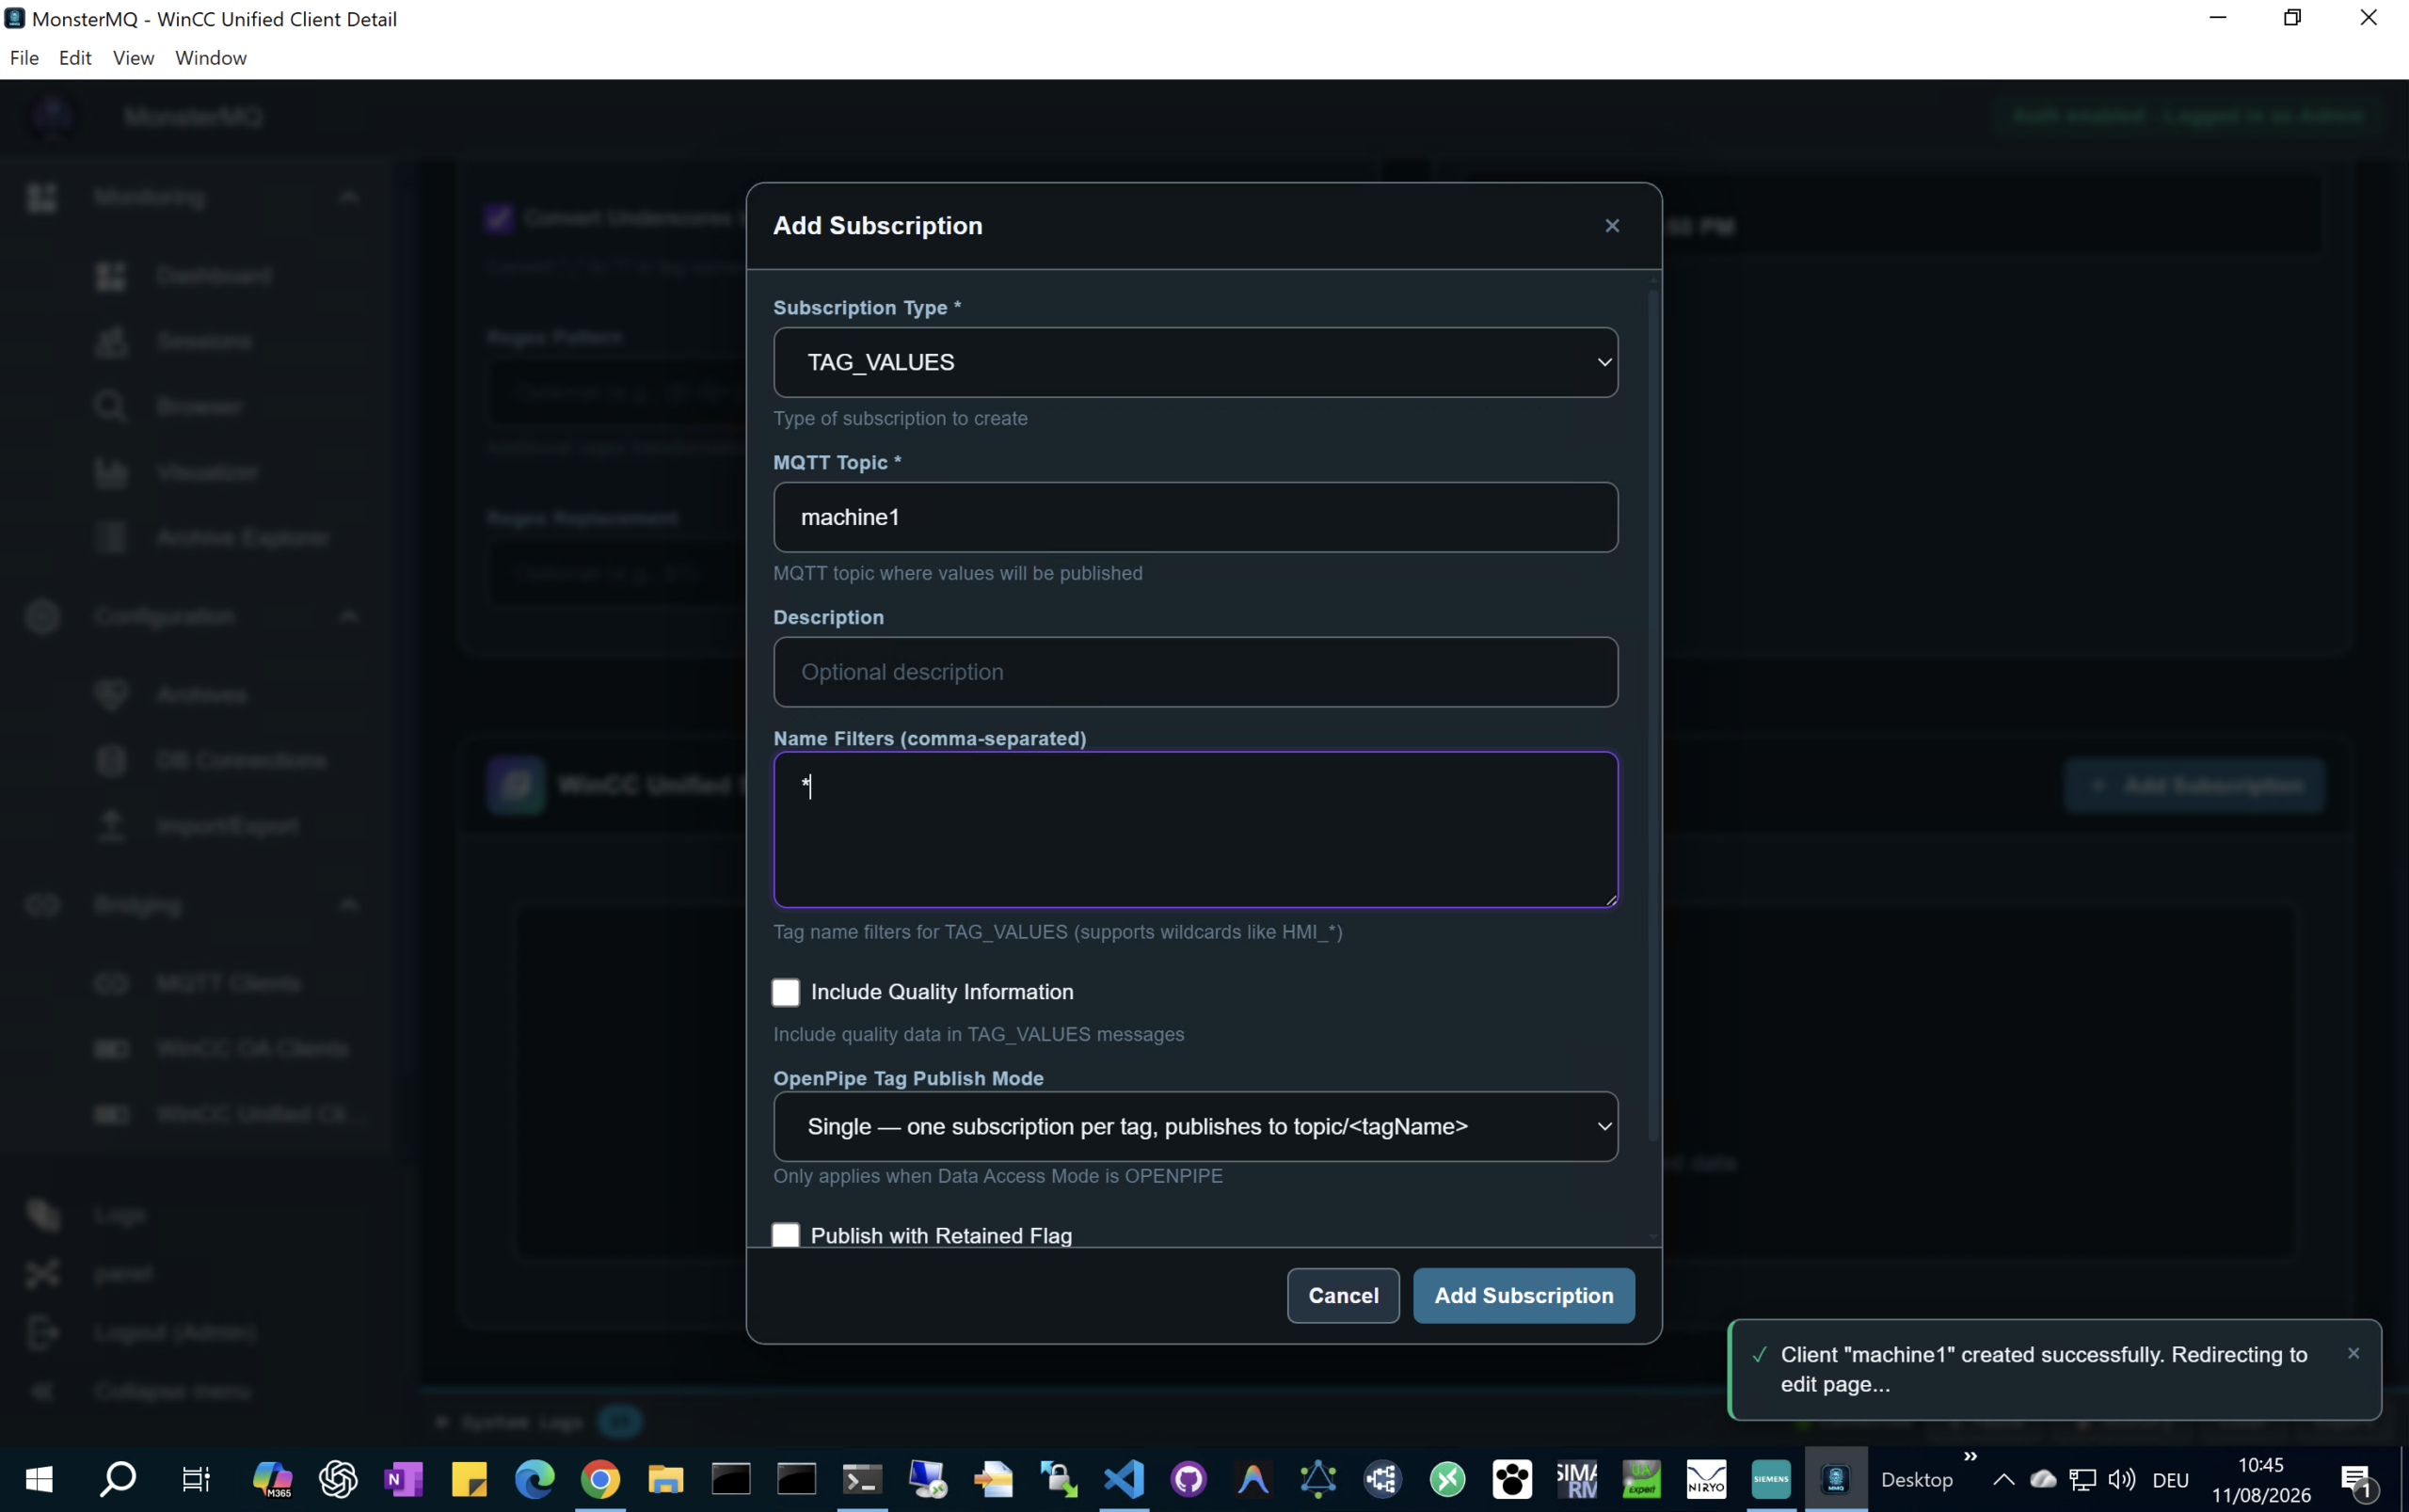
See how you can configure the HMI Tags to be exposed via MQTT
👉 https://youtu.be/C9KdrntWjec
⚠️ Use “/tmp/automation/HmiRuntime” as the Pipe Path!
MonsterMQ can run AI Agents – triggered by MQTT topics or on a schedule, with direct access to broker data in the context, and support for MCP Servers (including the internal one).
The agent can publish data to other topics – and that can trigger the next little agent. 🔄
Is this a good idea? Honestly, I don’t know yet – this is purely for learning right now.
The broker now has a NATS bridge integrated – you can receive messages from NATS and also publish to NATS.
For example, with simple wildcard subscriptions you can bring your topics straight into NATS – no extra glue code needed!
A big thanks to Kevin Joosten for this contribution!
‼️ And I added that MMQ can act as a NATS Server (NATS core 1.0). So, now NATS clients can connect to MonsterMQ and pub/sub to topics. NATS protocol is super simple.
This opens up some new integration scenarios where MQTT and NATS need to coexist in the same architecture.
Star it if you like it – and drop me a message if you’re using MonsterMQ in your setup!
What’s happening under the hood: 👉 MQTT topics are stored in memory 👉 Historical values are persisted in MongoDB Those features have been available in MonsterMQ for a long time…
The i3x interface just exposes all of that data via the i3x protocol!
💡 This means you get a full MQTT broker with structured, queryable data access via i3x – all in one place.
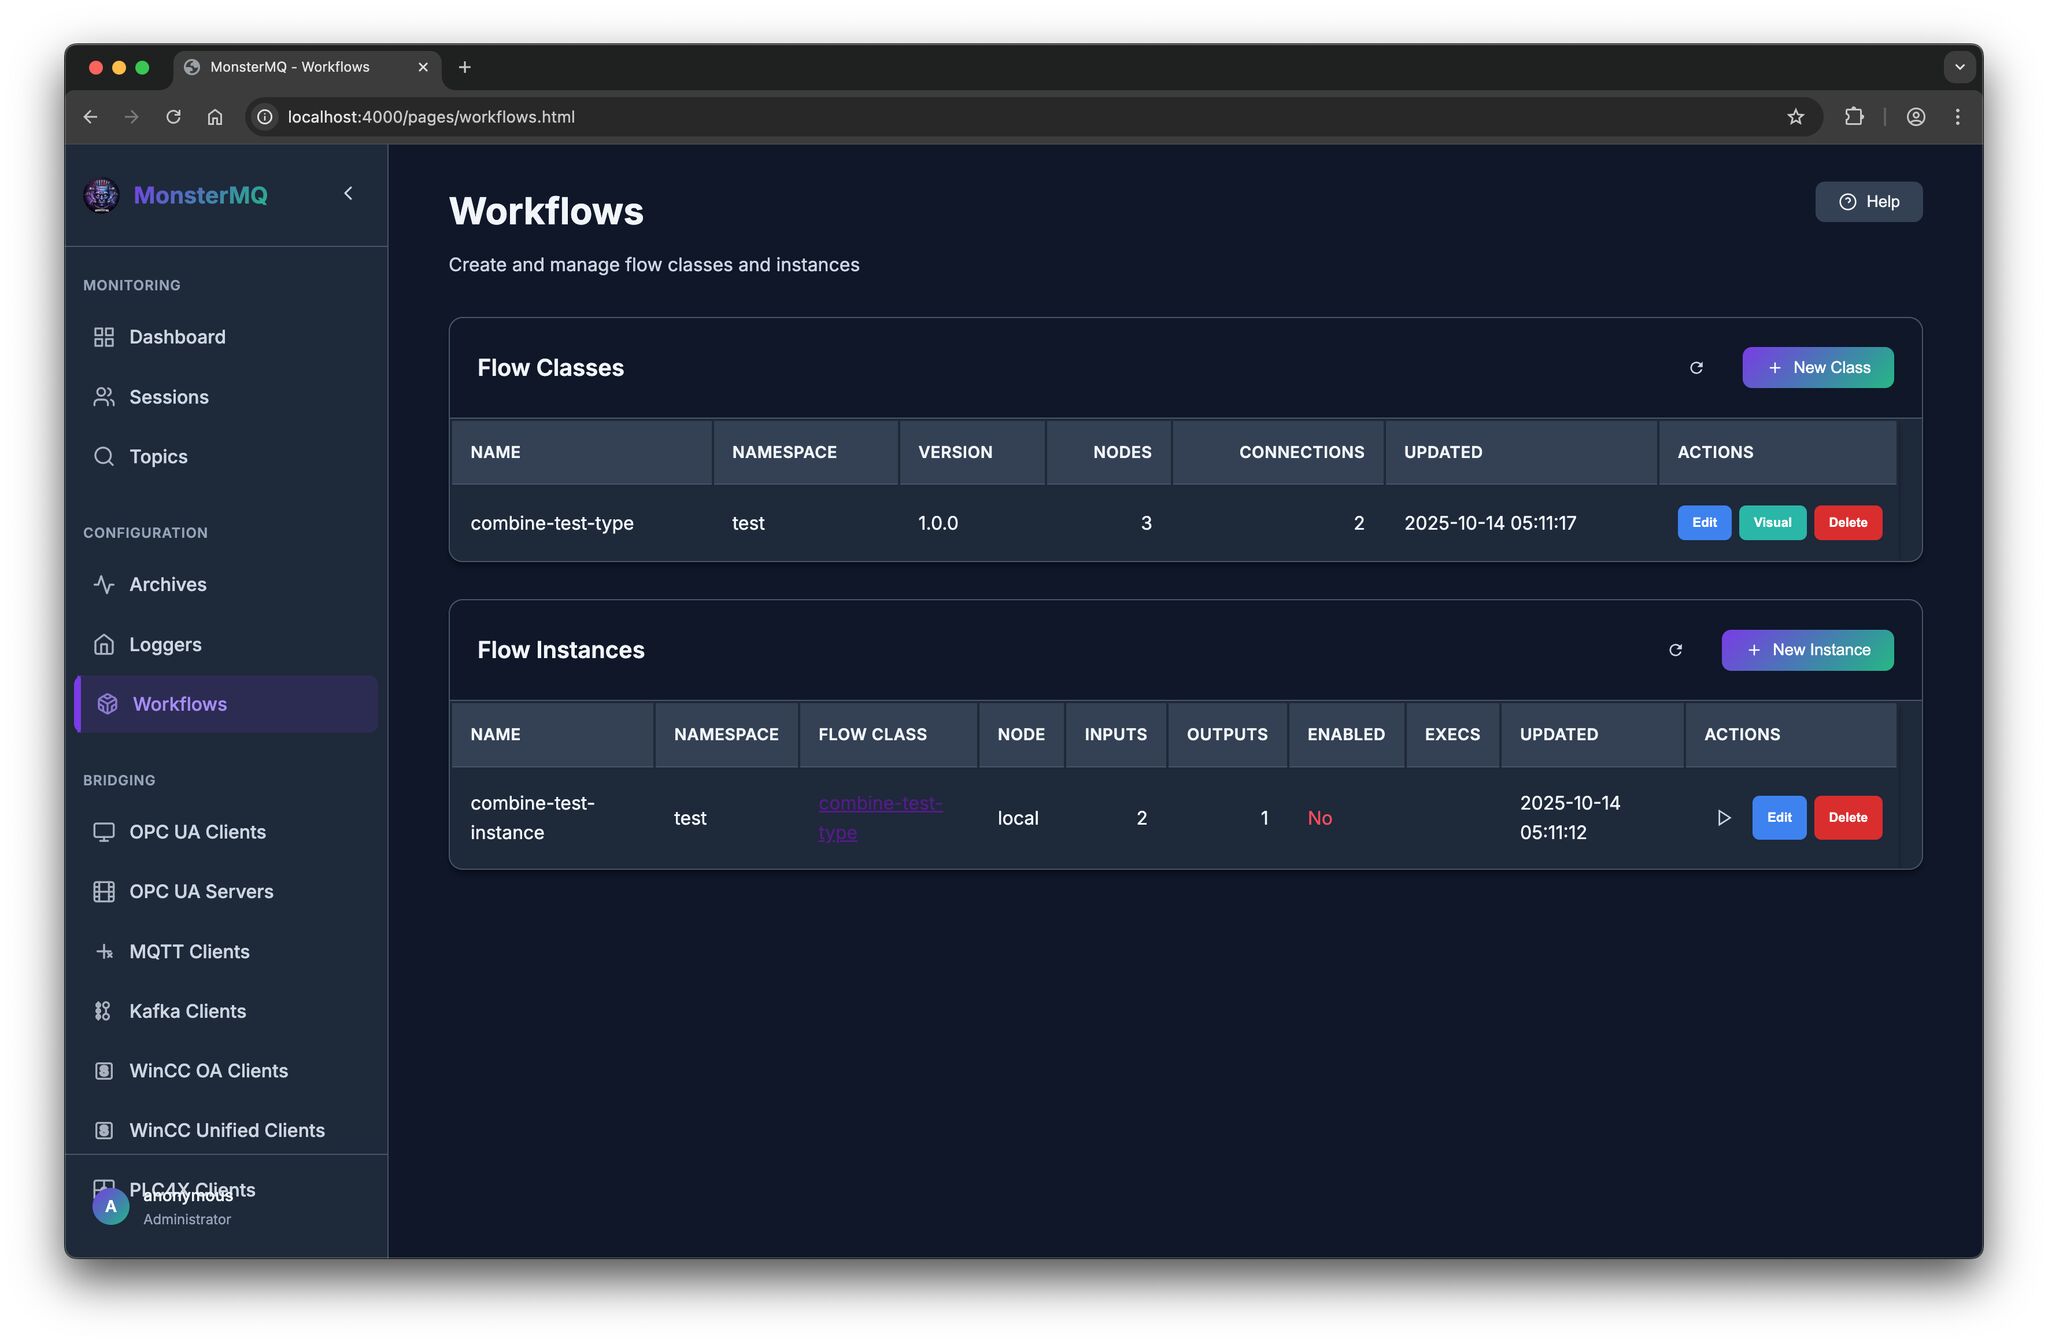
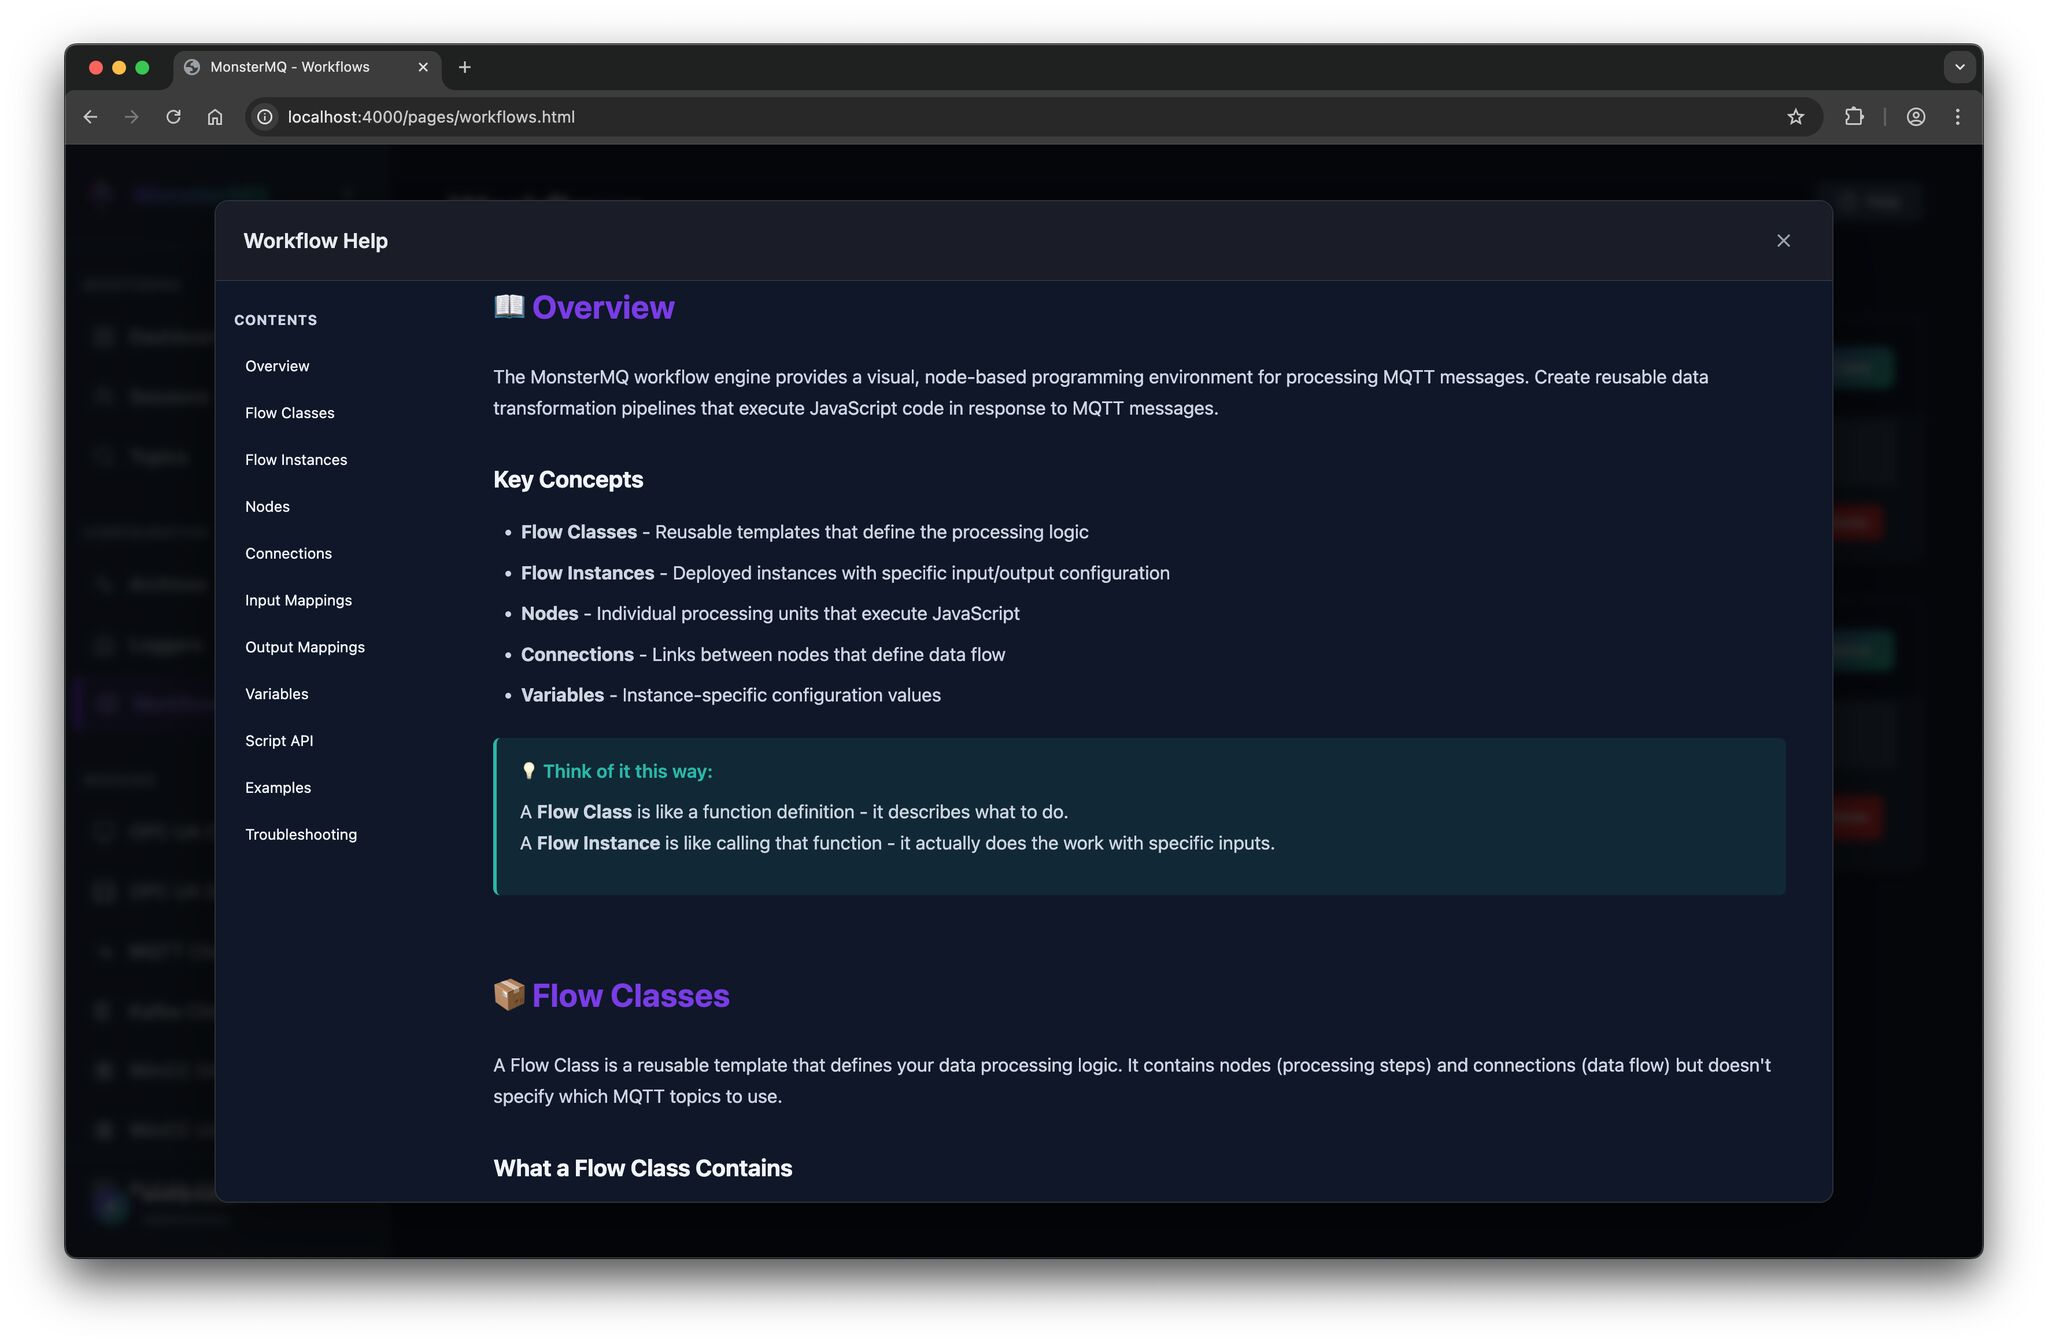
I’ve added a first version a workflow engine that lets you define custom business logic directly inside the broker: 🔹 React on multiple input topics 🔹 Write your logic in JavaScript, more functions 🔹 Publish results to output topics
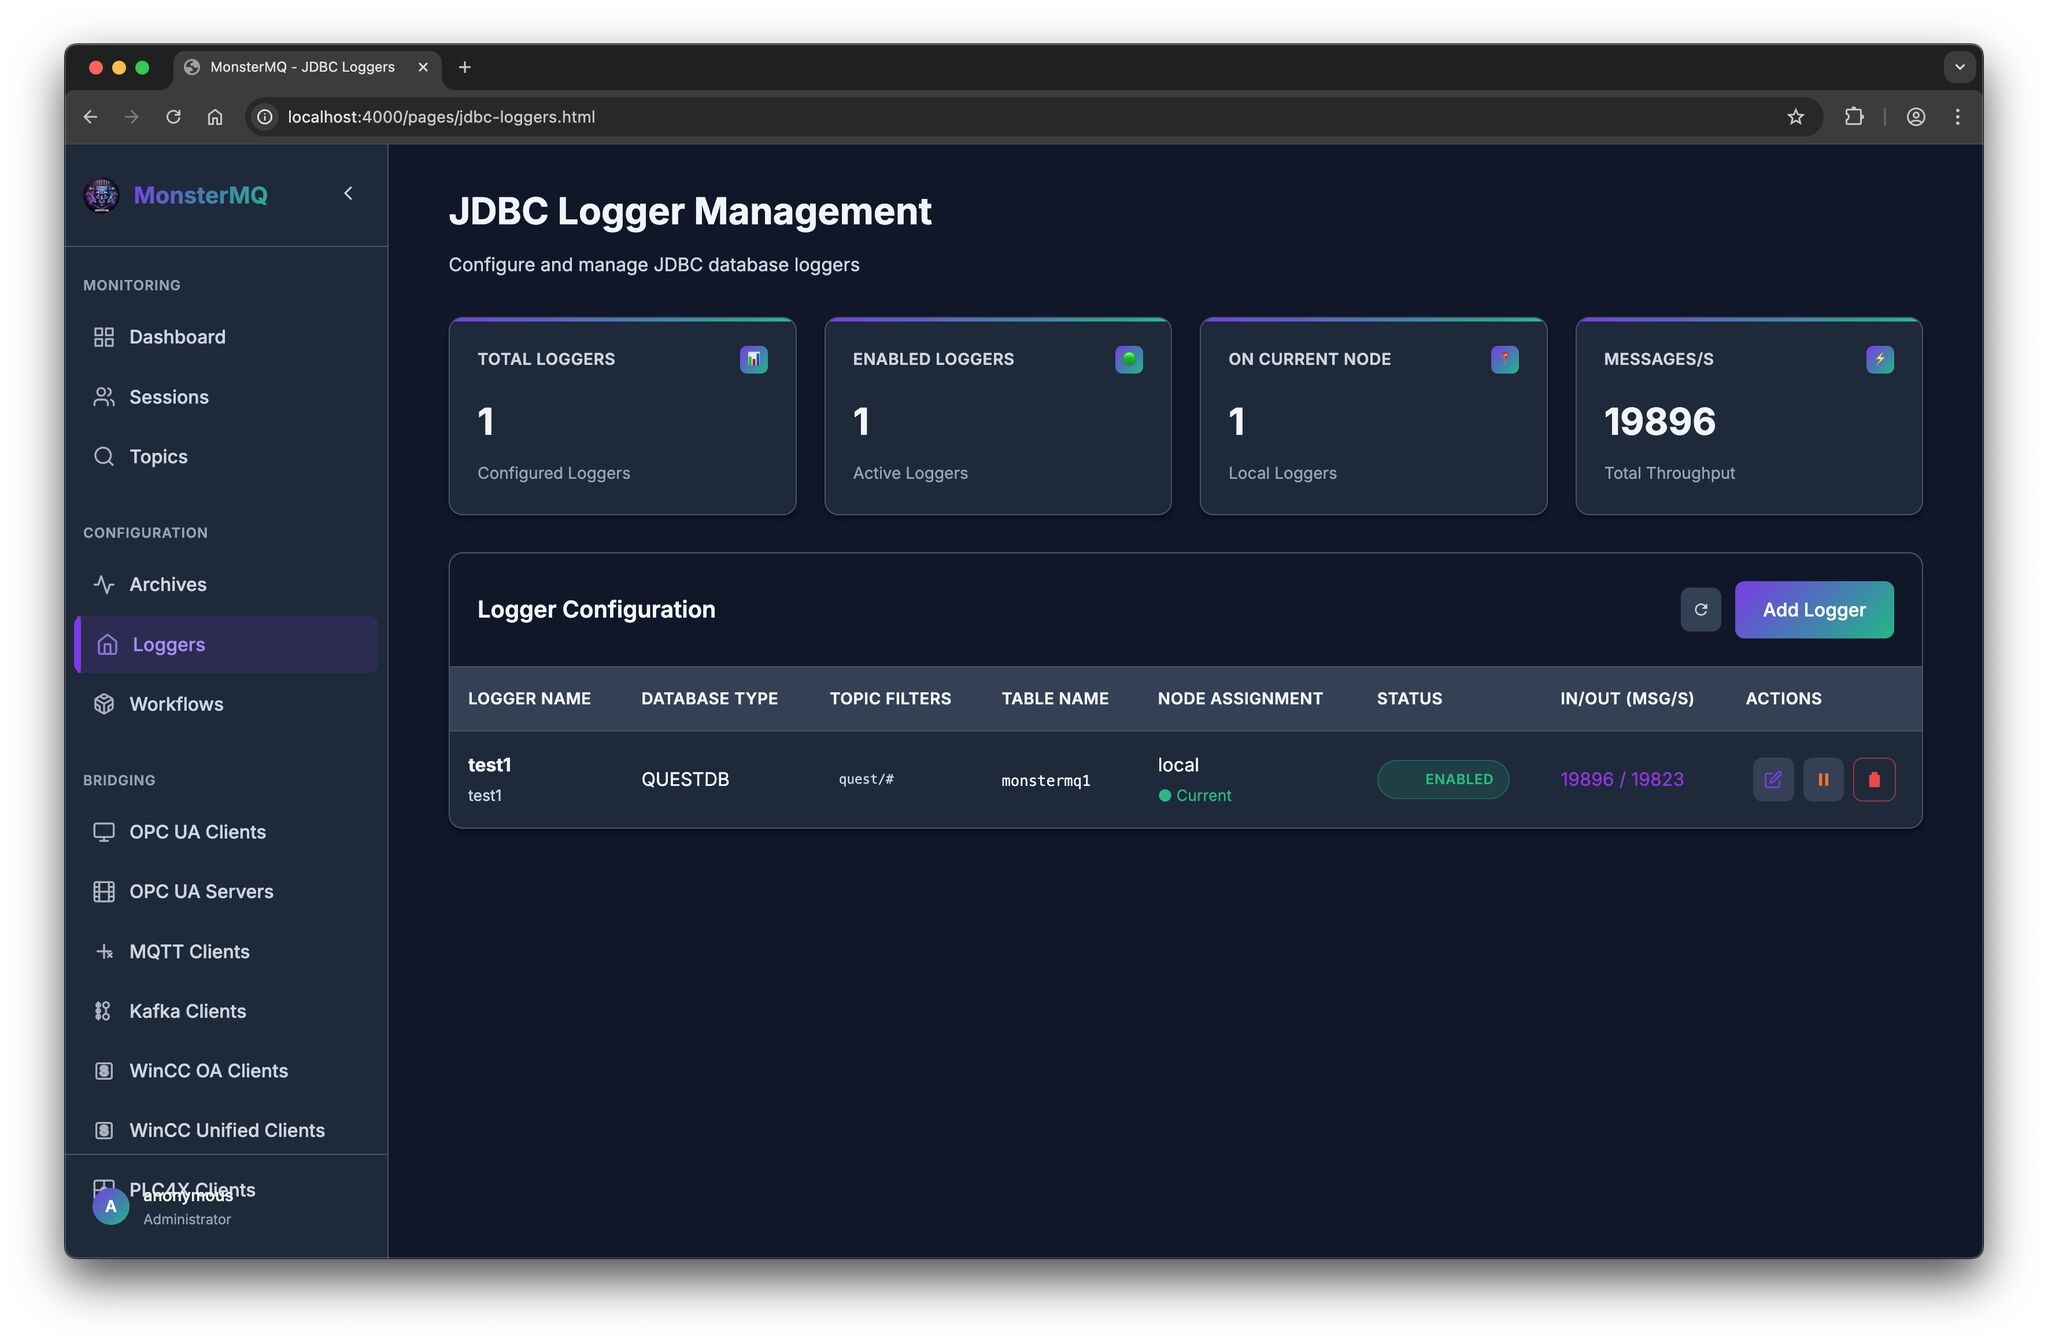
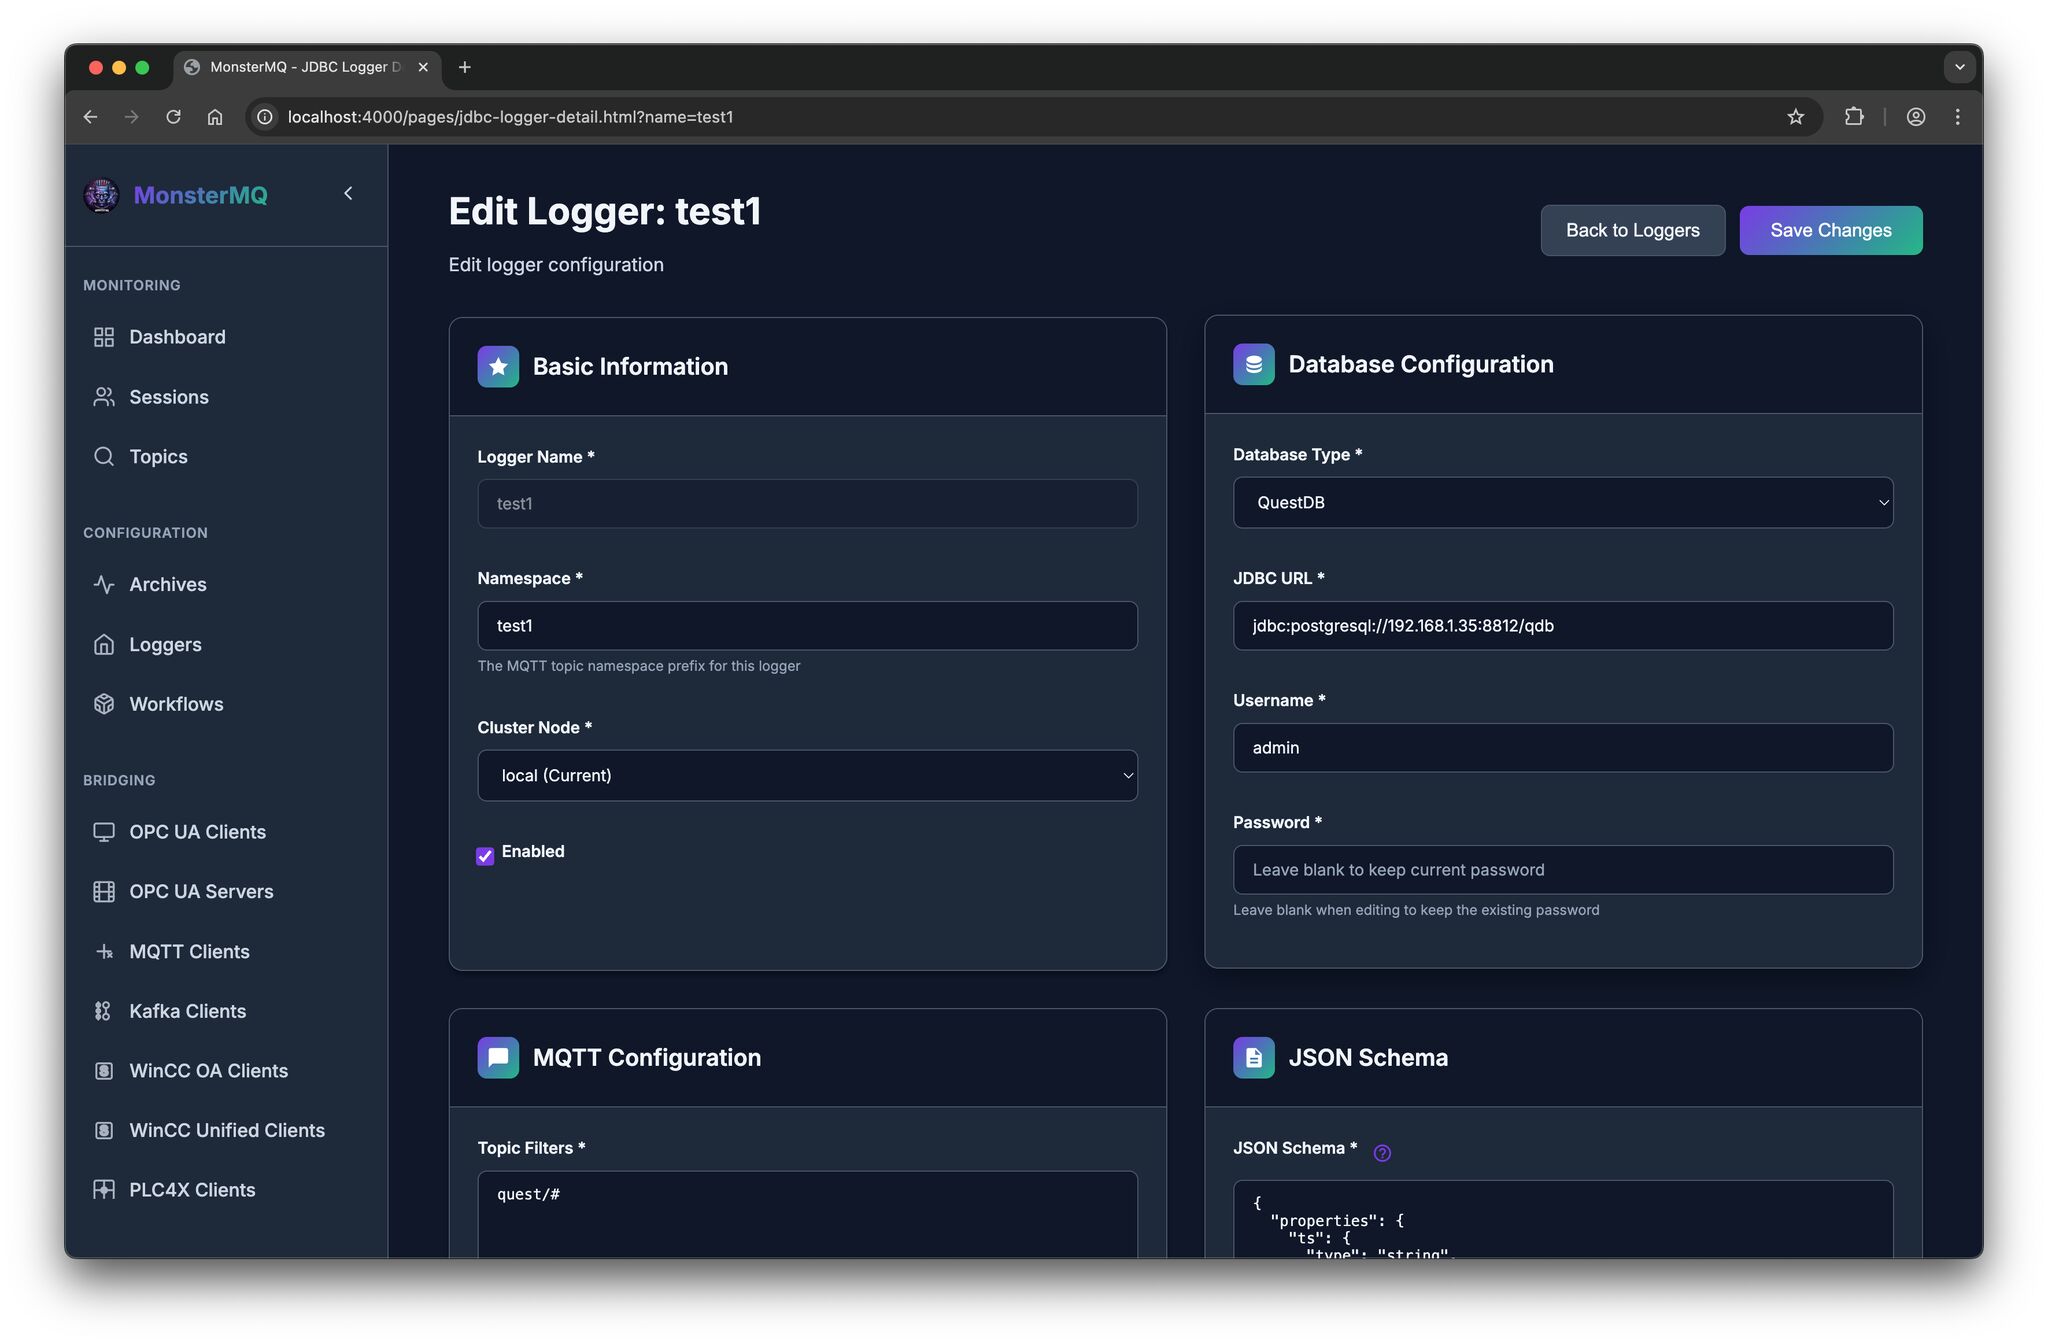
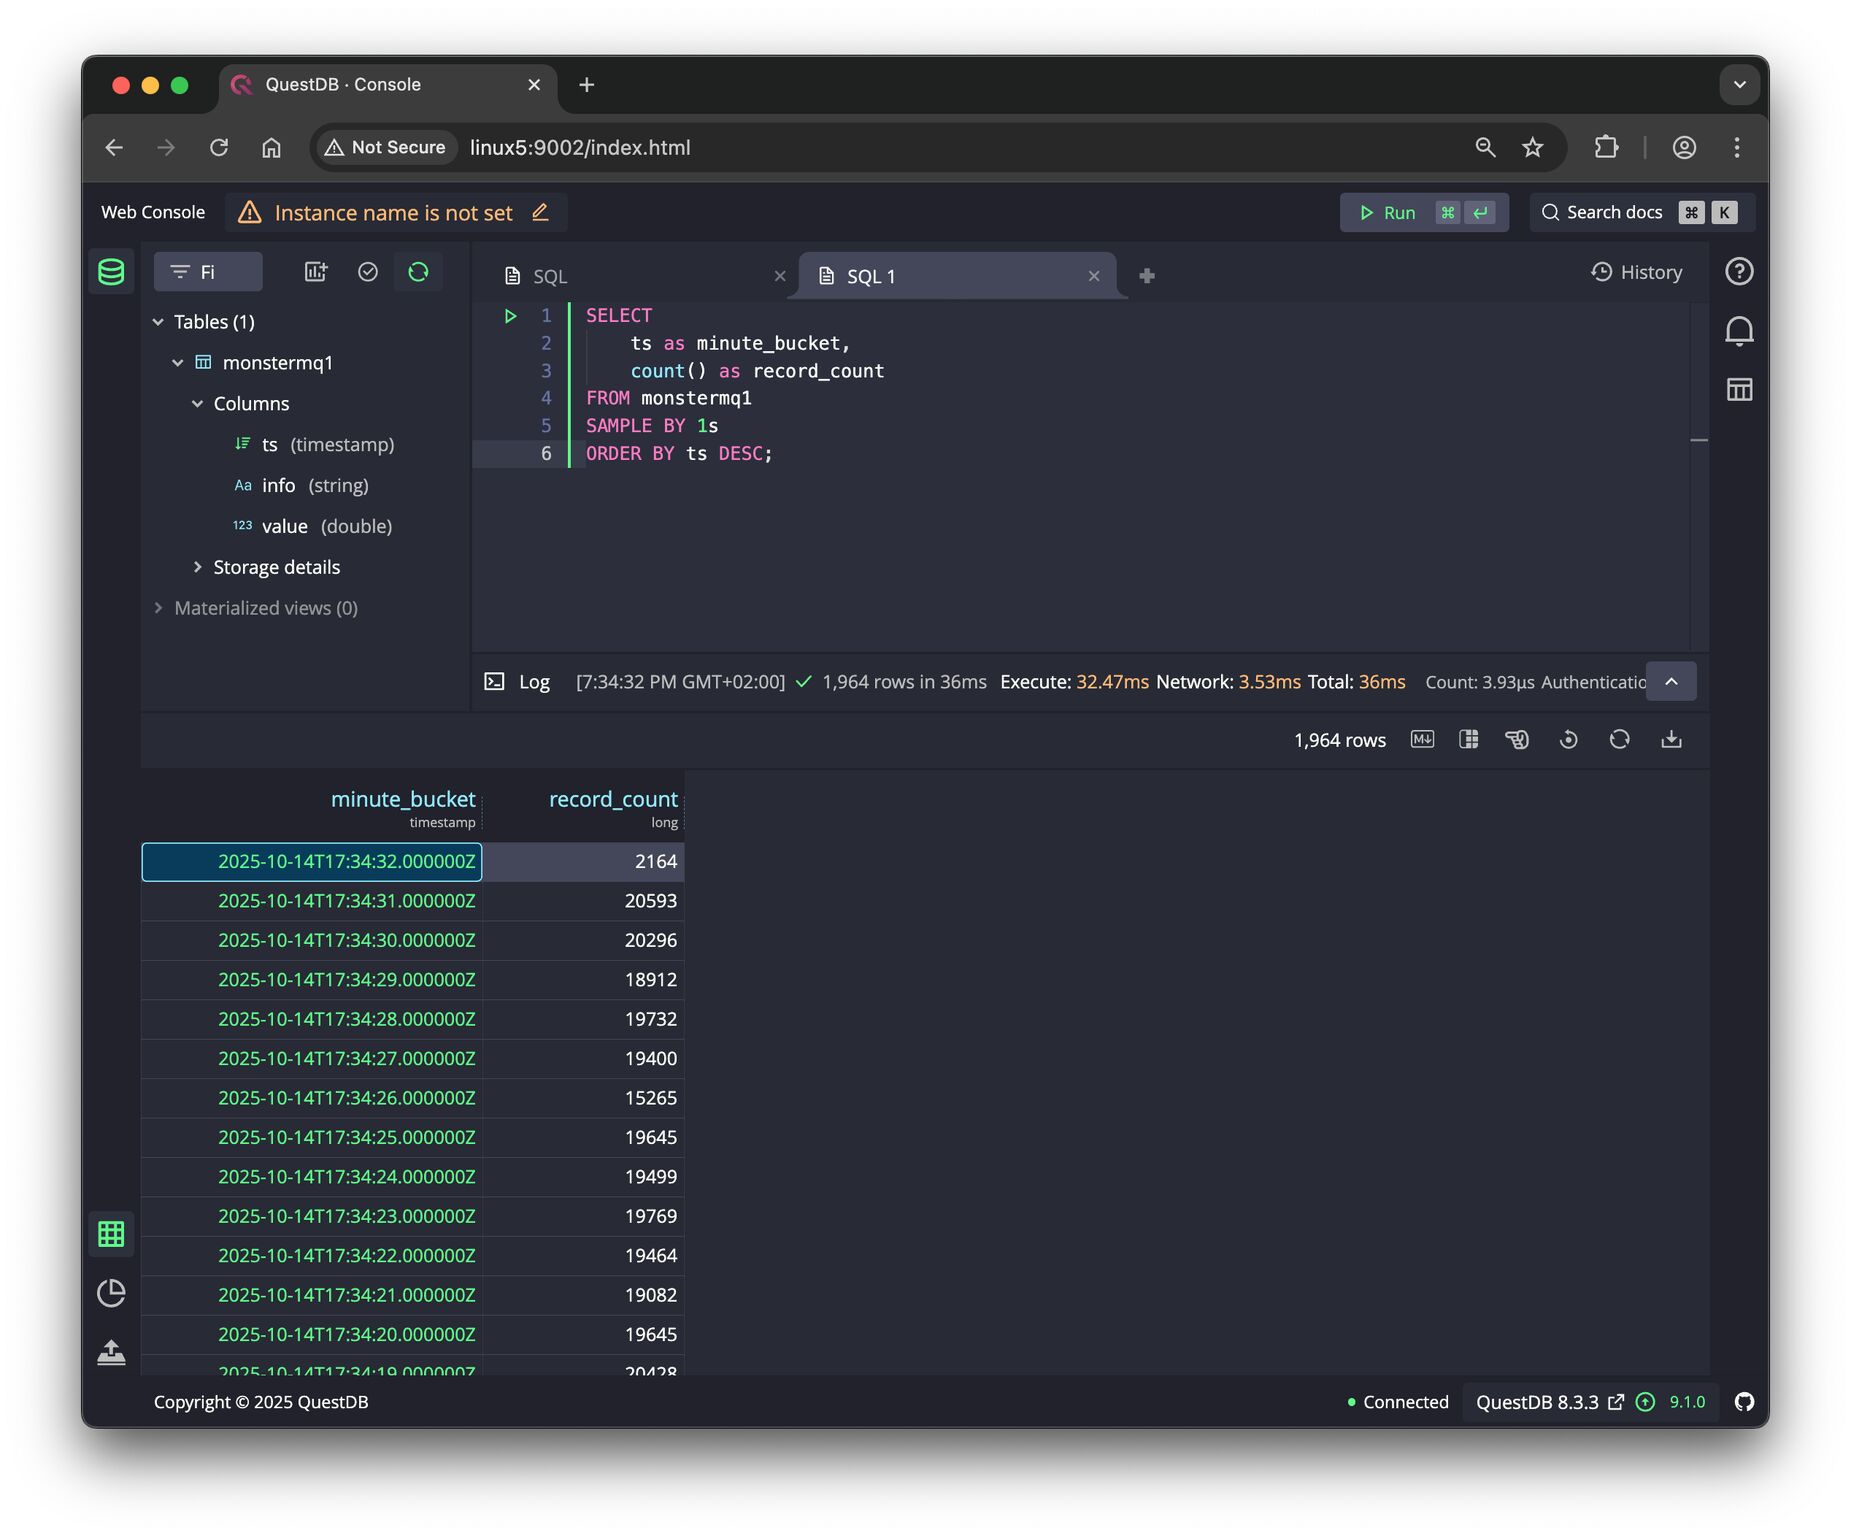
💾 And there is now a JDBC-based Data Logger with store and forward.
It currently supports JSON payloads, with a JSON schema, you can define how fields map to columns in your database tables.
See the pictures, a simple test with 30 Python clients publishing topics to the broker. It stores 20 kHz of data into a QuestDB instance without issues.
It’s a simple way to process and store data where it flows – no need for external services or function frameworks.
👉 MonsterMQ.com 👉 give a star on GitHub if you like it. thx.
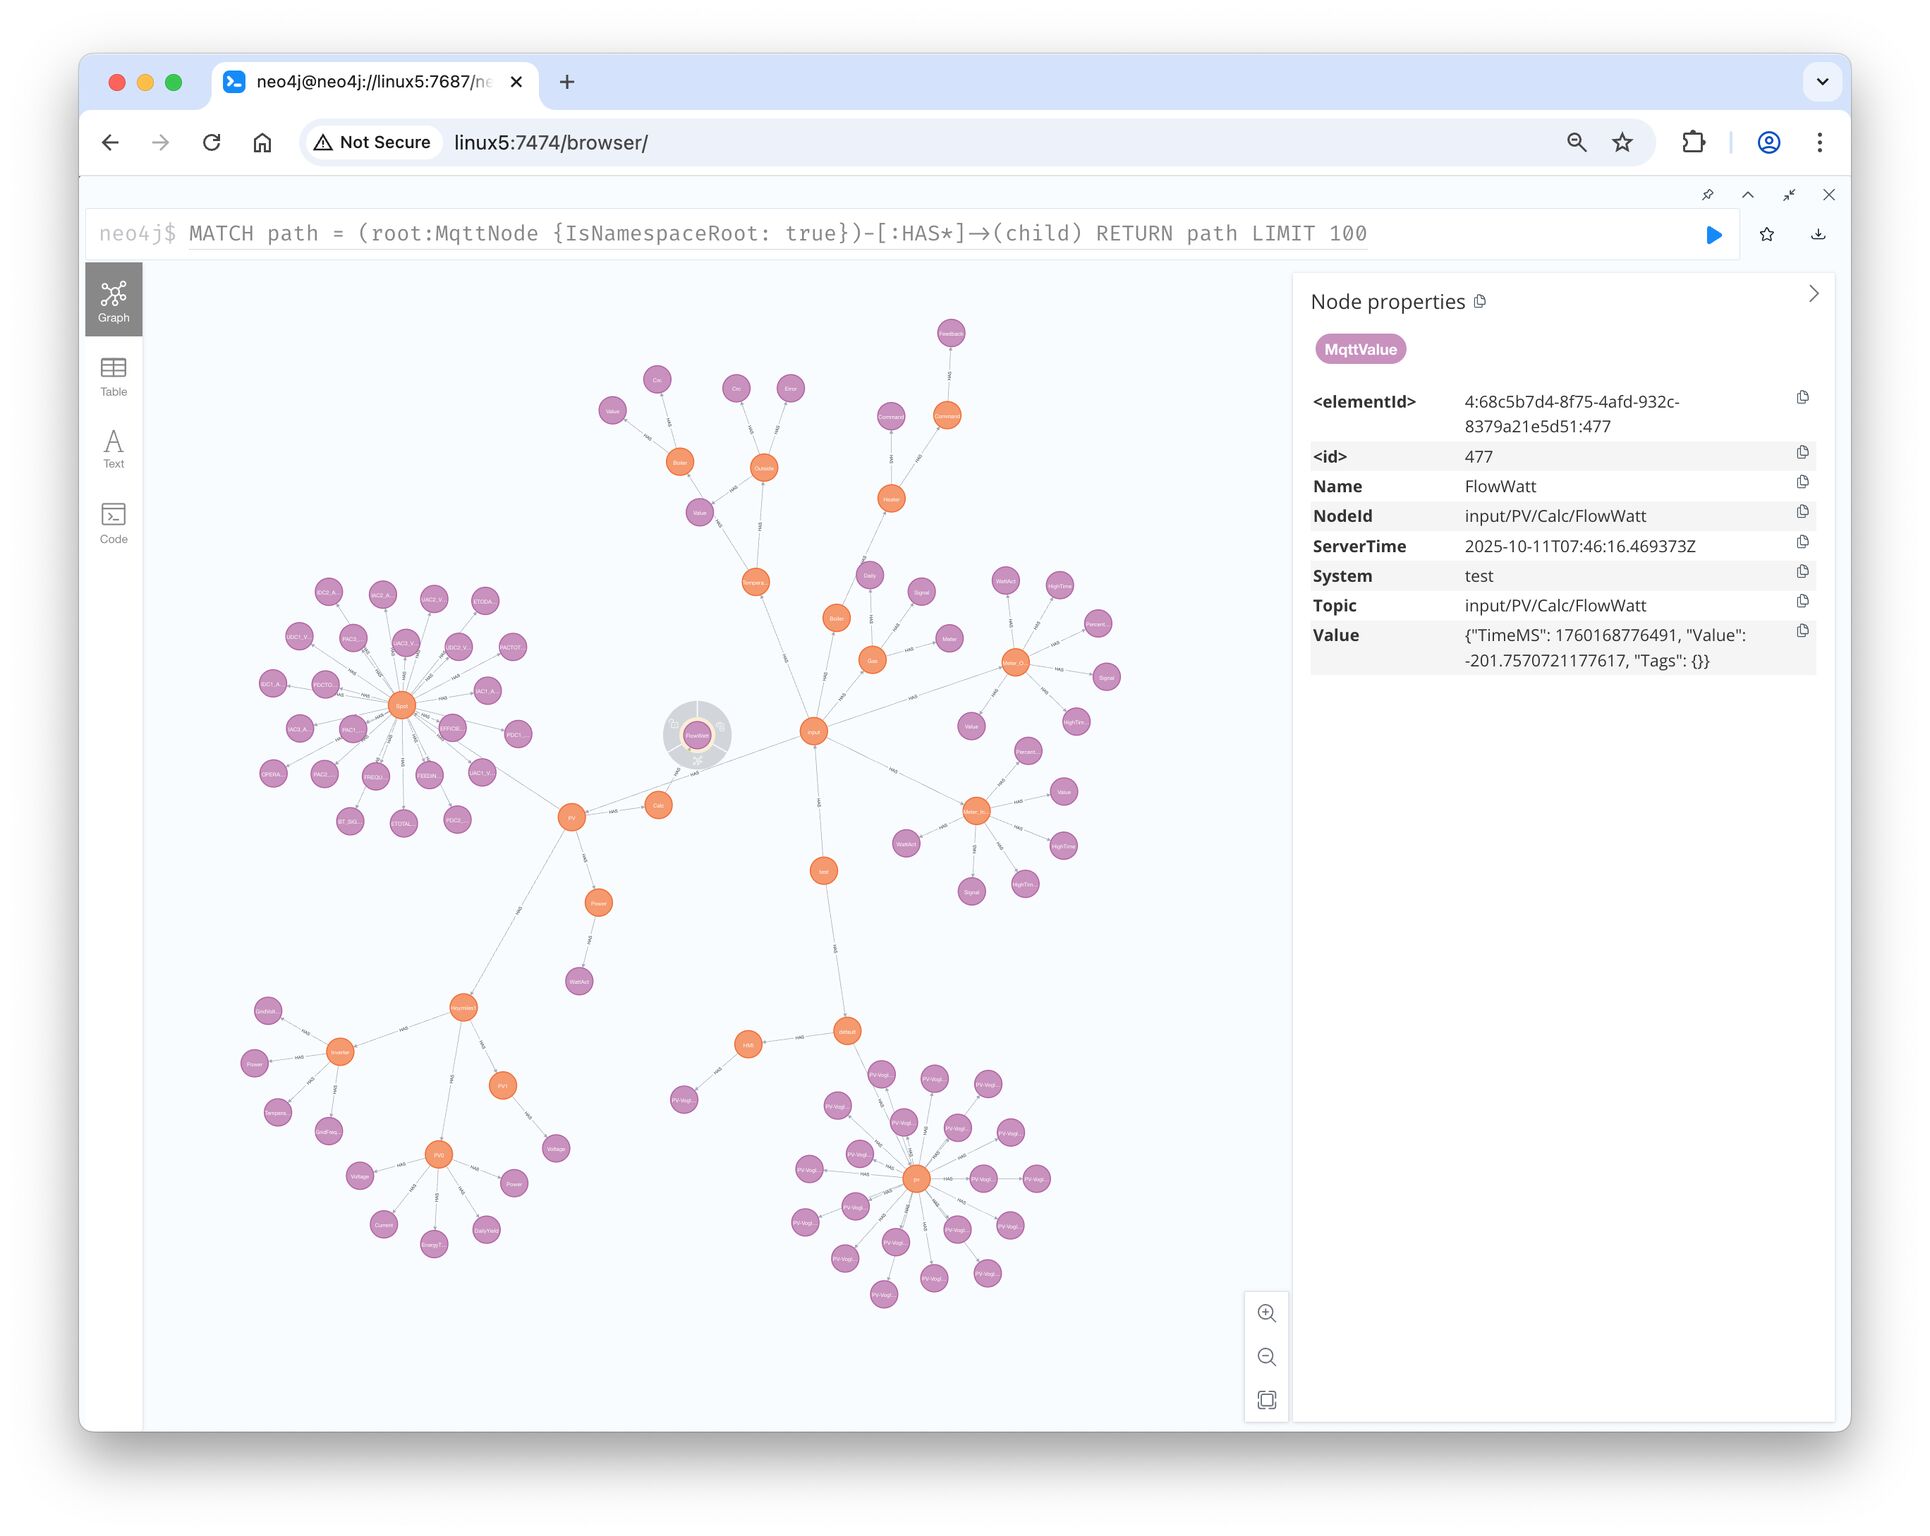
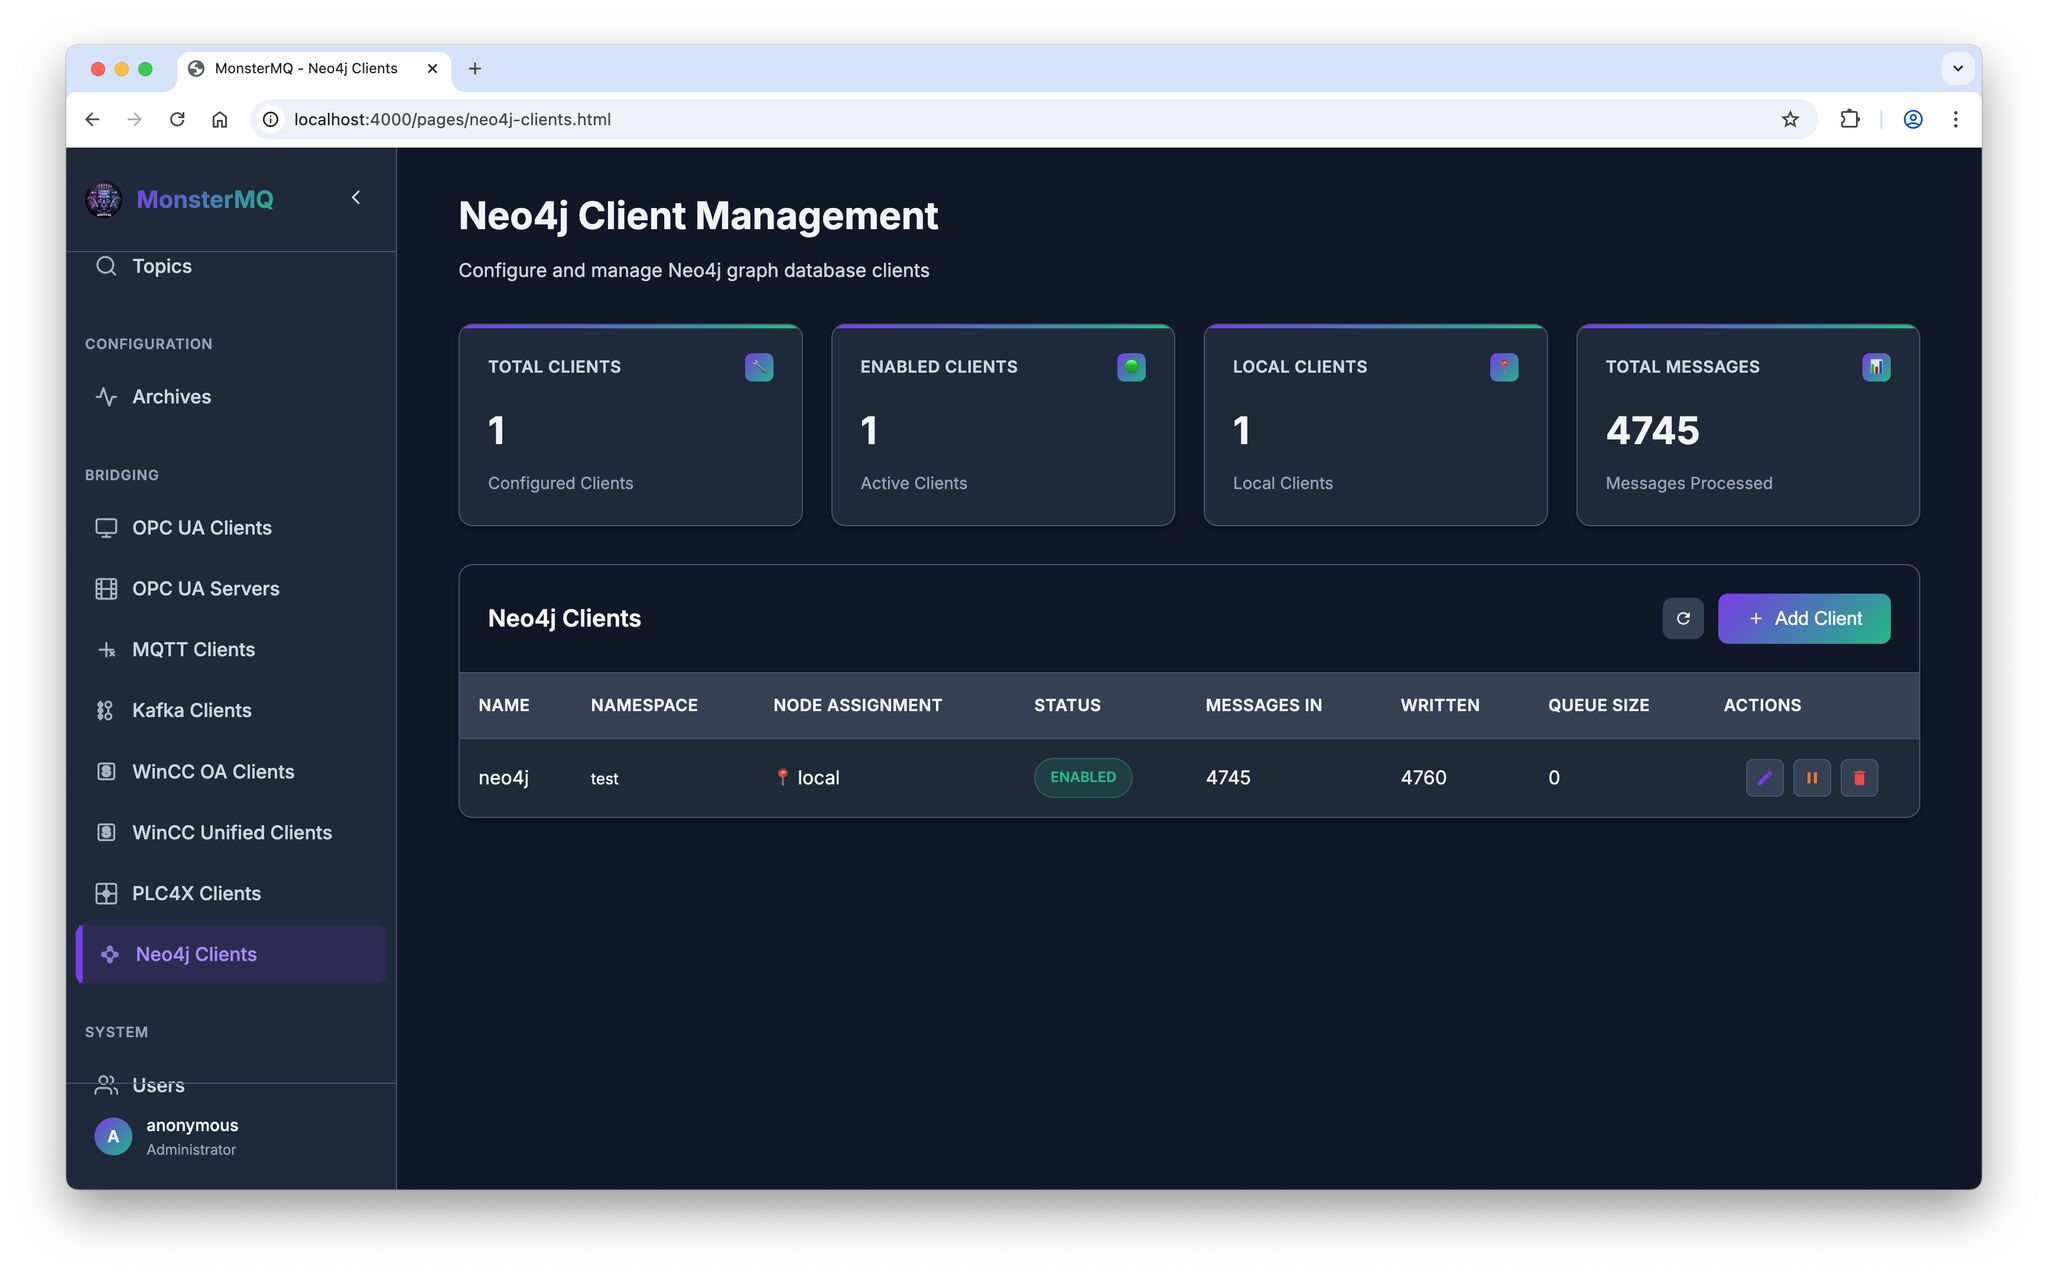
I’ve merged the functionality for bringing MQTT UNS topic trees to Neo4j. Previously part of my Automation-Gateway open source project.
👉 Now, MonsterMQ can push namespaces from the broker into a Neo4j graph database.
💡 Graph databases can help LLMs understand context and relationships better. This integration makes it easy to link your UNS data with other graph data, enriching the context of your factory and process information.
⚠️ But be careful – don’t overload your database with too many writes 😉